

TL;DR
- The formula: Your mentions ÷ all tracked-brand mentions × 100. Count a brand once per answer.
- The setup: Freeze the prompts, brands and engines. Log every answer.
- Real data: WebFX had 14.3% share of voice. Track only four agencies and it's 27.8%.
- Sample size: On 50 answers, a 20% rate has a margin of about 11 points.
- Cadence: Scan weekly. Act on a change that holds for three scans.
Does AI name your brand? Check your site.
How do you measure share of voice in AI search?
Three steps:
- Run the same buyer prompts on each AI engine.
- Count the brands each answer names.
- Divide your mentions by the mentions of all the brands you track.
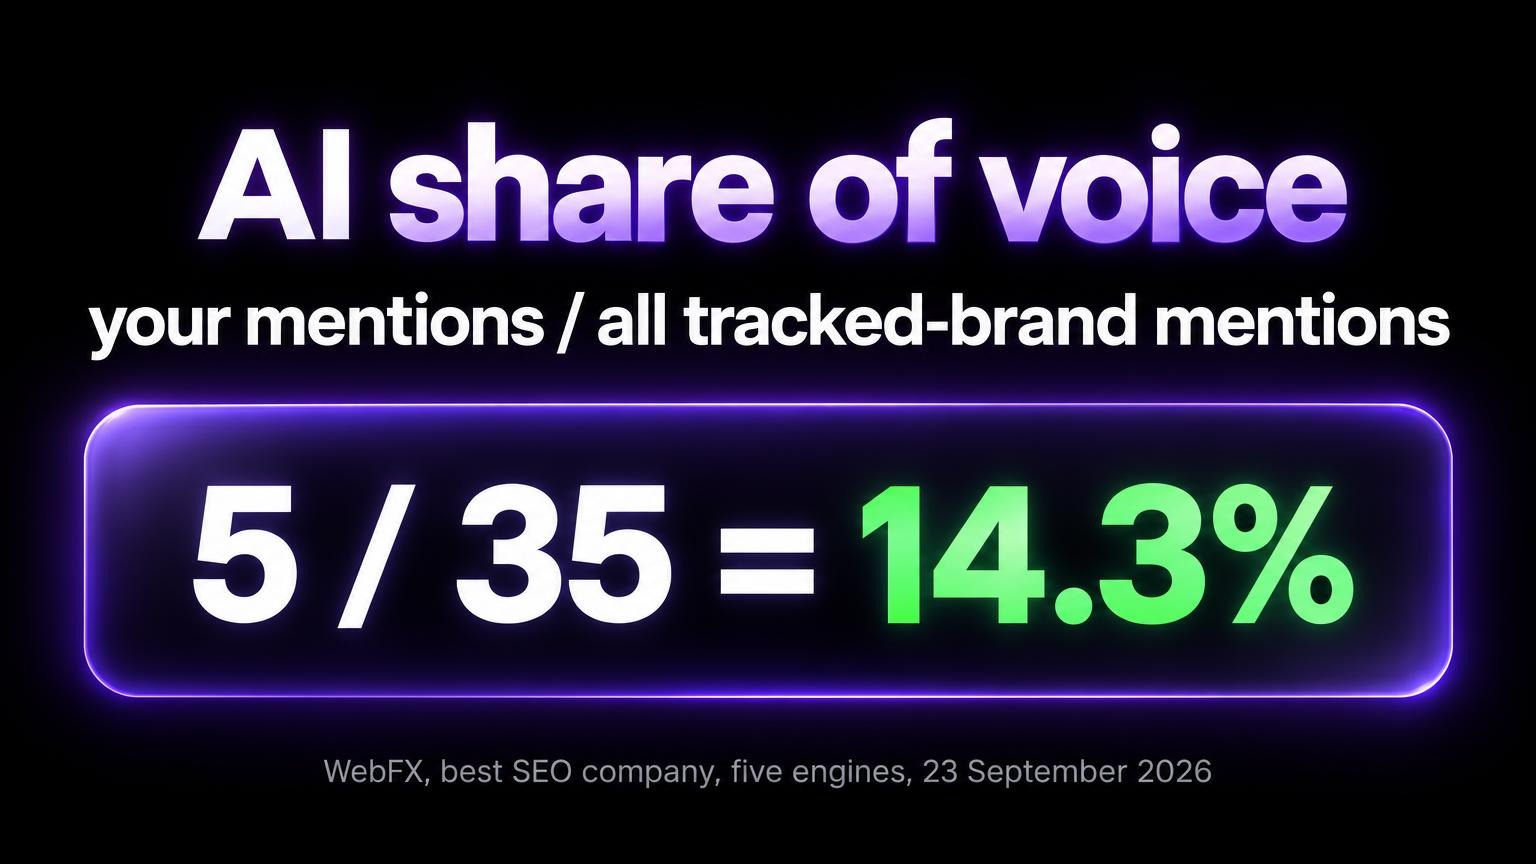
AI share of voice = your brand mentions ÷ all tracked-brand mentions in the same answers × 100
Simple. But two things make it messy.
AI answers change on every run. And tools use different formulas under the same name.
Search Engine Land has argued that vendors hide the denominator behind a small, arbitrary set of prompts.
So own the denominator. Freeze the prompts, brands and engines. Store every answer. Print the counts under each number.
(For ads, search and social: how to calculate share of voice.)
The Formula for AI Share of Voice
One counting rule first.
Count a brand once for each answer that names it. However often the answer repeats the name. Ahrefs uses the same rule.
Then three numbers. Report each one separately.
- Mention share of voice = your mentions ÷ all tracked-brand mentions × 100
- Mention rate = answers that name you ÷ all answers × 100
- Citation share = cited URLs on your domain ÷ all cited URLs × 100
A mention is your name in the answer text. A citation is a link to a source.
Two details:
- Keep every cited URL in the citation denominator. Review sites and forums included.
- Put position in its own row. The order of brands in an answer doesn't belong in the headline.
(AEO metrics covers mention rate and the engine split.)
Where does the term come from? Advertising: your media spend as a part of all spend in the category. Each channel counts its own inventory. So keep one row per channel.
How to Measure It in Four Steps
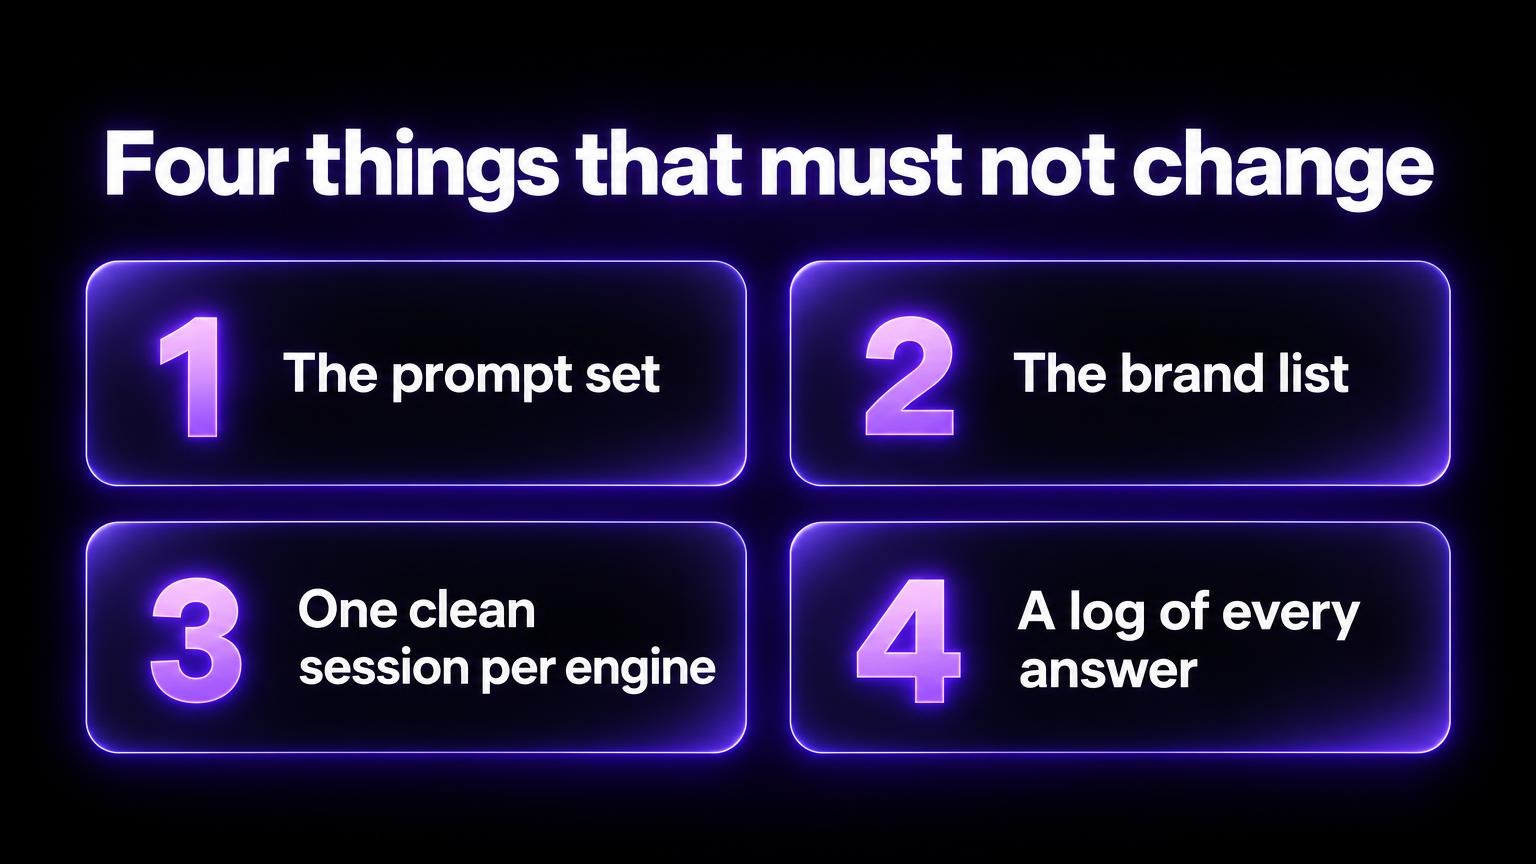
Four things must not change between scans.
A frozen prompt set
Start with 25 to 50 prompts. The ones a buyer in your category asks before they know your name.
Where to get them: sales calls, support tickets, forum threads. Not your keyword list.
(The free keyword research tool finds buyer questions. How to measure brand visibility in AI lists the prompt types.)
Keep prompts with your brand name out of the set. They inflate the number.
Discovered Labs audited five client prompt sets (May 2026). It found this inflation in all five.
The most extreme one: a reported mention rate of 10.8%. On the prompts that didn't name the brand: 1.9%.
A brand list and an alias list
The brands you track are the denominator.
- Choose three to five brands. The ones you lose deals to.
- Record other named brands in a separate column. That's how you spot a new rival early.
- Changed the list? Start a new trend line. Add a brand, and the share of every other brand falls. Nothing changed in the answers. (The real example shows it.)
Then write down each form of each name that counts. Company name. Product name. Common misspellings. Domain.
Now two people count an answer the same way.
One clean session for each engine
Each engine gets its own row. Here's why.
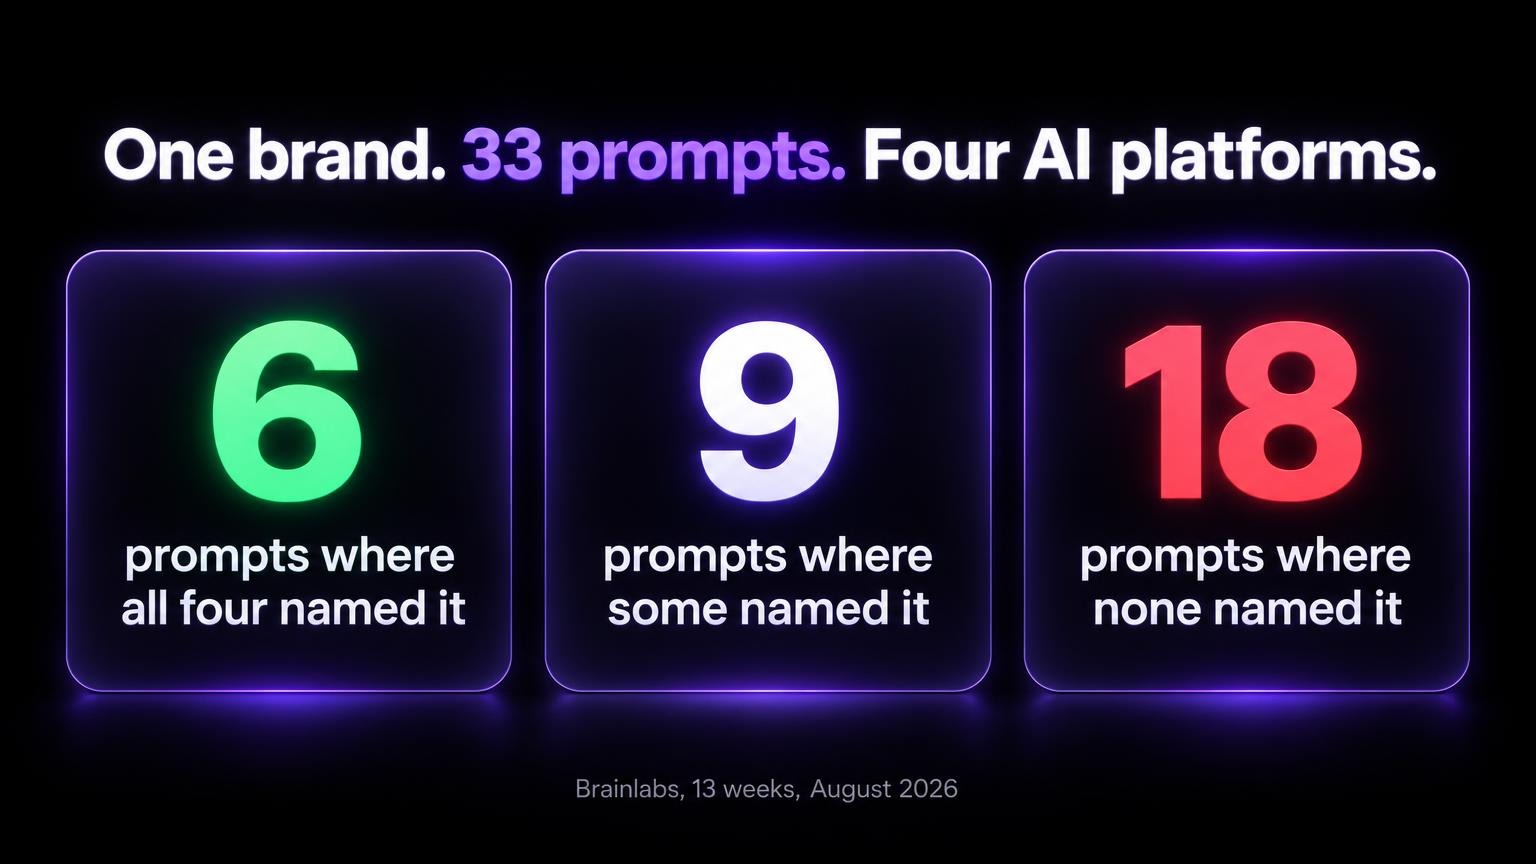
A Brainlabs test (August 2026) tracked one anonymized B2B brand. 33 prompts. Four AI platforms. 13 weeks.
- The brand appeared on all four for only 6 prompts.
- On none for 18.
Use a clean session. OpenAI's help page on web search in ChatGPT says ChatGPT can use your approximate location and saved memories when it rewrites your prompt into search queries.
So:
- Turn memory off.
- Record the country, the language and the model name the engine shows.
- Sell in more than one country? Run the set once for each.
A log of every answer
One row per answer. (The second line is a template, not data.)
Date	Engine	Model shown	Country	Prompt	Brands in order	Cited URLs	Saved answer
2026-10-02	ChatGPT	as shown in the app	US	best SEO company for SaaS startups	Brand A; Brand B; Brand C	https://example.com/page	answers/2026-10-02-chatgpt-p01.txt
Save the full answer text. If you can't open the answer again, you can't defend the count.
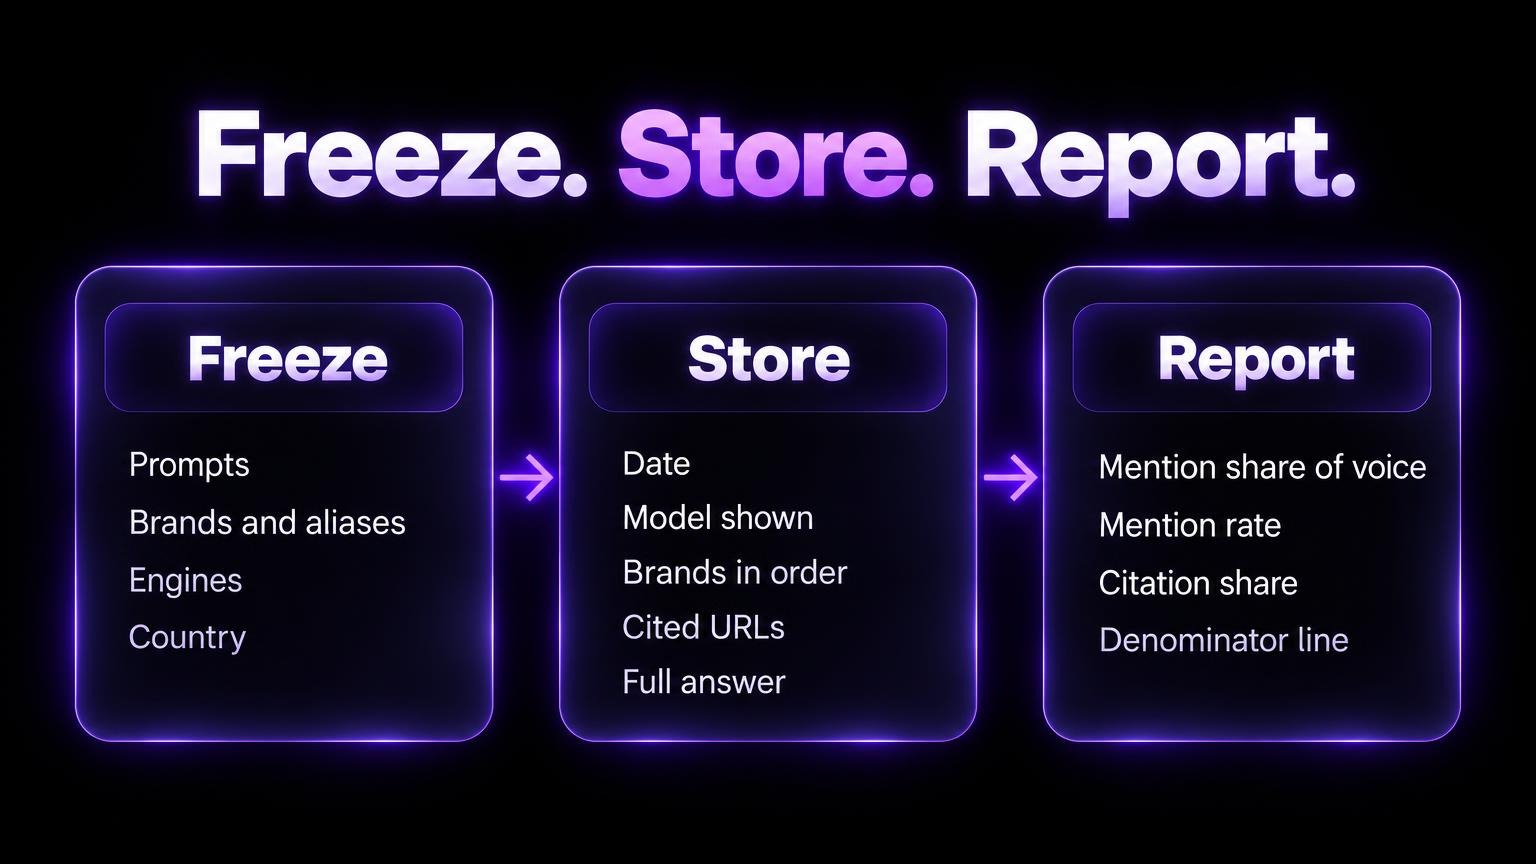
The honest part is one line below each figure: prompts, engines, runs, dates, and the brands in the set.
A Real Example With Five Engines
Real numbers now.
The public AI SEO Tracker leaderboard lists the brands each AI engine names for a "best X" question. Scanned monthly.
Here's "Best SEO Company", scan of 23 Sep 2026. (Live page.)
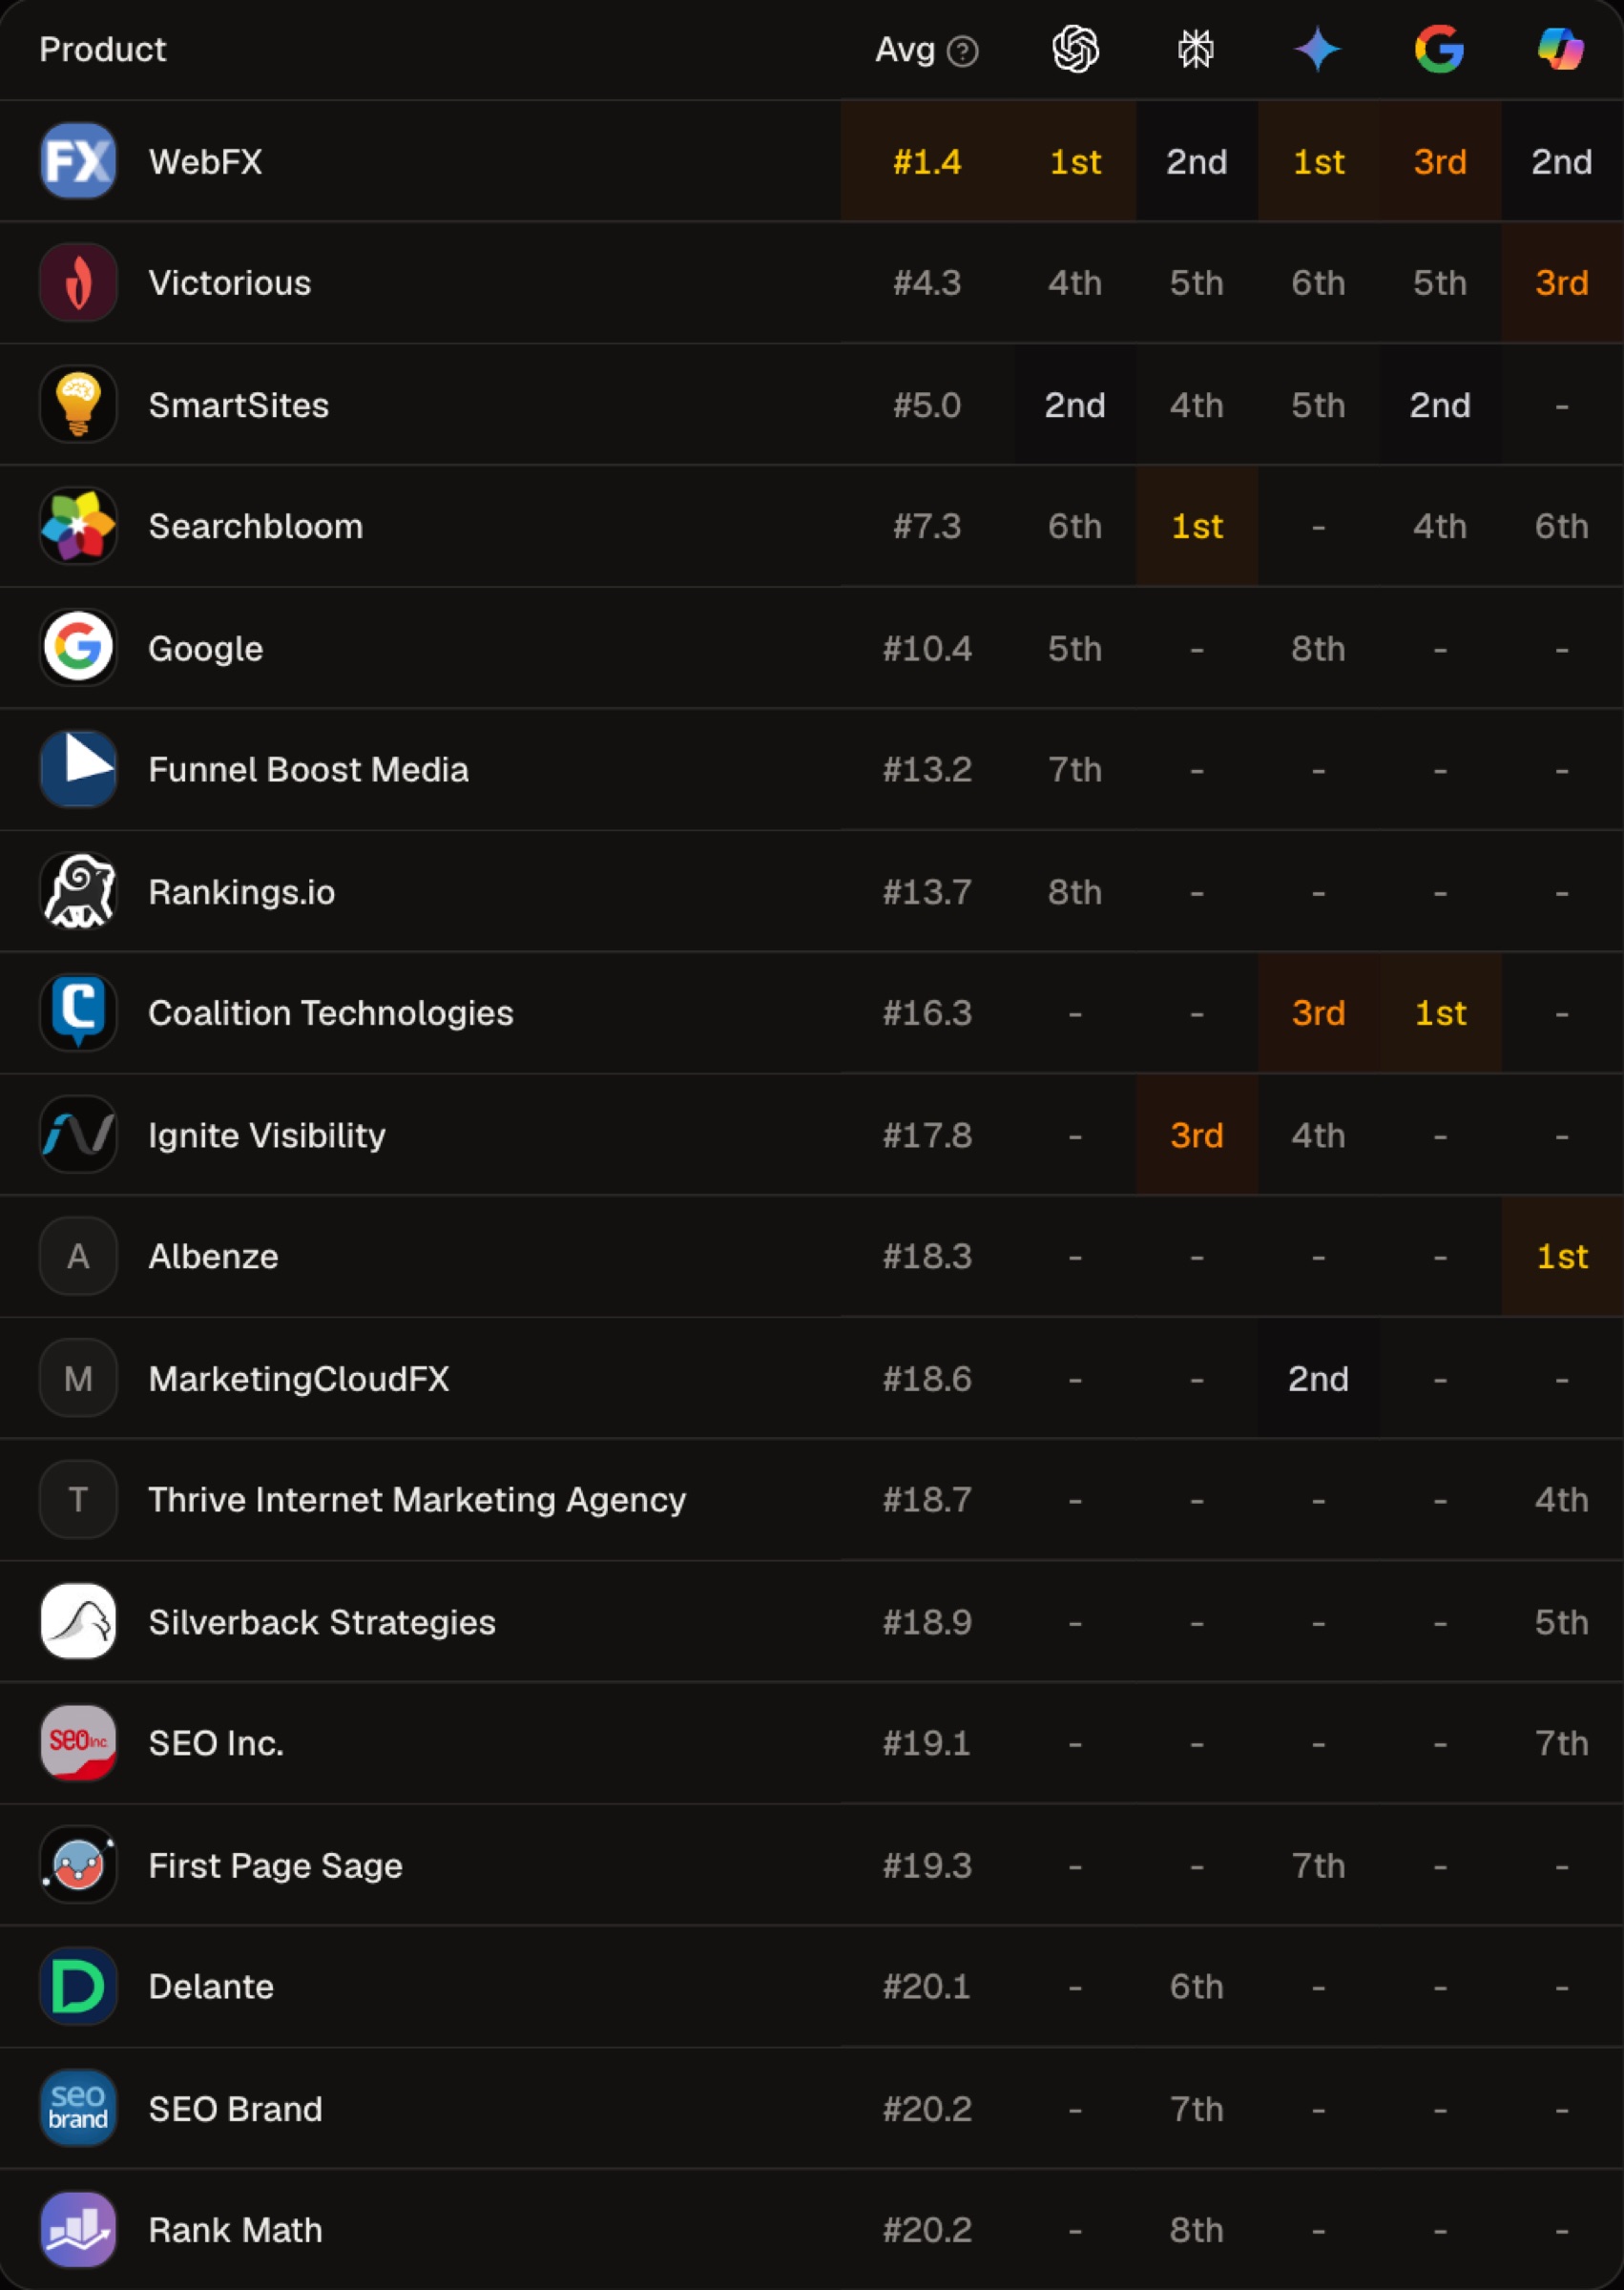
How many brands did each engine name?
- ChatGPT: 7
- Perplexity: 8
- Gemini: 8
- Google AI Overviews: 5
- Copilot: 7
That's 35 mentions from 18 brands. One mention per brand per engine's answer.
| Brand | Engines naming it (of 5) | Share of voice (of 35) |
|---|---|---|
| WebFX | 5 | 14.3% |
| Victorious | 5 | 14.3% |
| SmartSites | 4 | 11.4% |
| Searchbloom | 4 | 11.4% |
| Google, Coalition Technologies, Ignite Visibility | 2 each | 5.7% each |
| Eleven brands named once | 1 each | 31.4% together (2.9% each) |
| Total | 35 mentions | 100% (rounded) |
Four lessons in that table.
1. Mention rate is not share of voice.
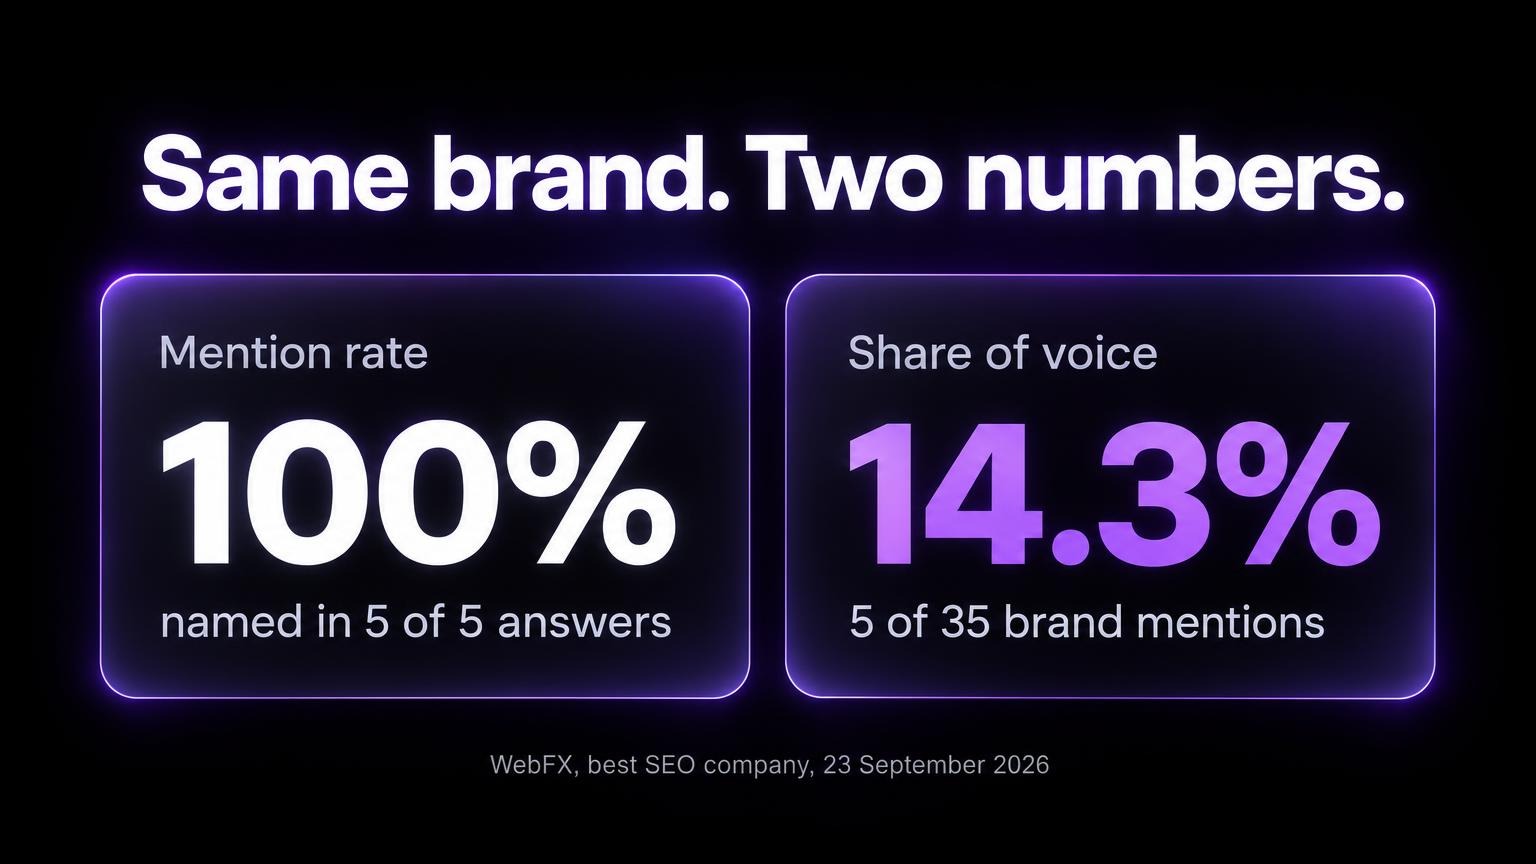
WebFX is named in 5 of 5 answers. Mention rate: 100%.
Its share of voice? 5 ÷ 35 = 14.3%.
2. The brand list is the denominator.
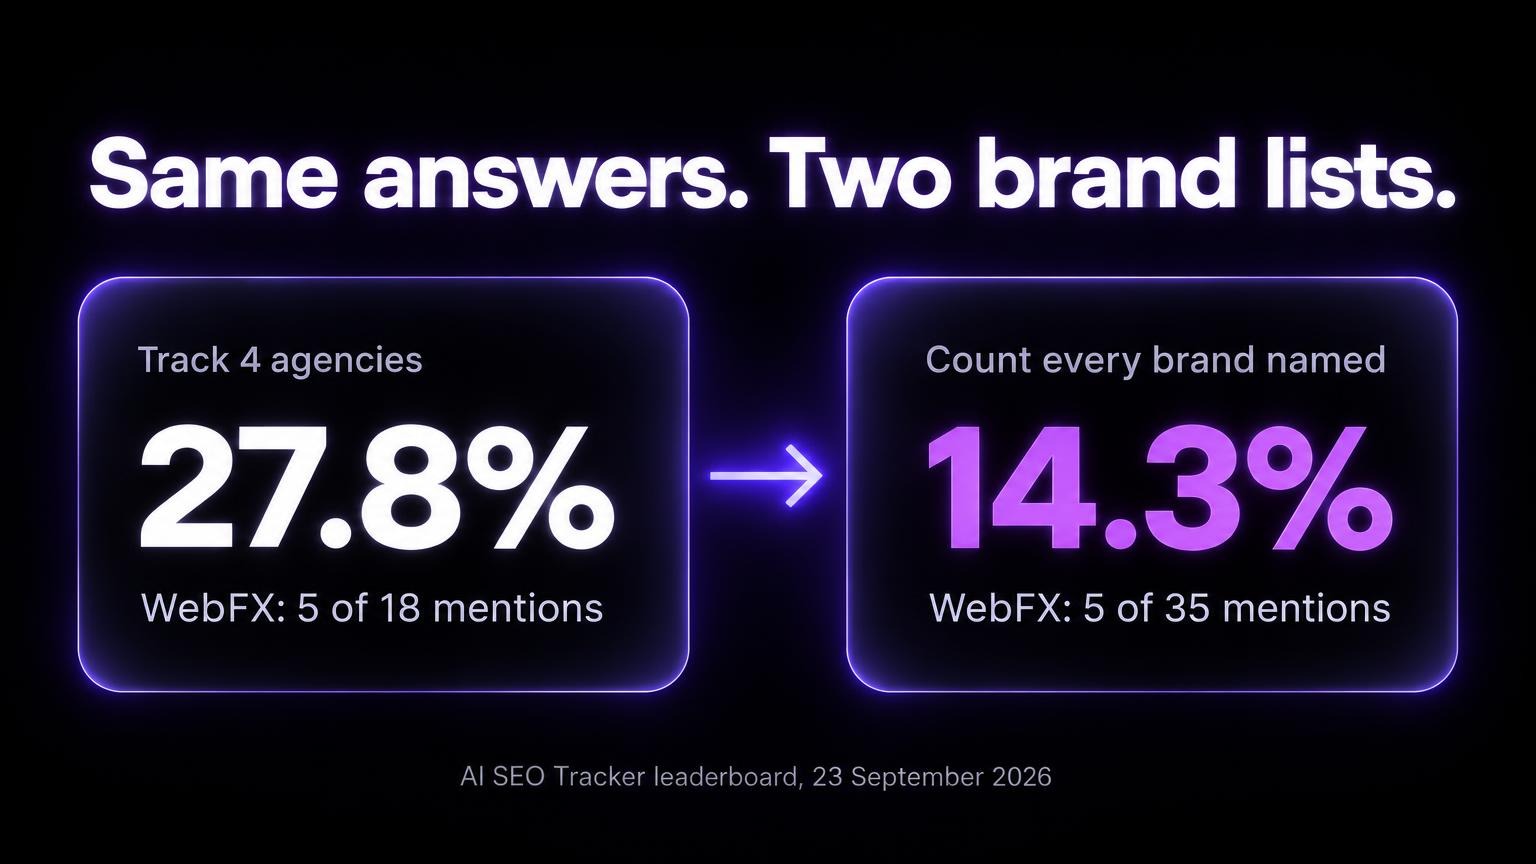
Track only WebFX, Victorious, SmartSites and Searchbloom. Together: 5 + 5 + 4 + 4 = 18 mentions.
- Four brands tracked: WebFX has 5 ÷ 18 = 27.8%.
- Every named brand counted: 5 ÷ 35 = 14.3%.
Same answers. Different list.
3. One engine's list is not the market.
Eleven of the 18 brands came from one engine only. So report each engine in its own row first.
4. Mentions and citations are different numbers.
The scan lists 23 cited pages. (A page that three engines cite counts once.)
- 20 of the 23 are listicles.
- Nine sit on the domain of an agency that's also in the ranking.
Citation share here = pages on the brand's own domain ÷ 23.
| Brand | Mention share (of 35) | Citation share (of 23 pages) |
|---|---|---|
| WebFX | 14.3% | 4.3% (1 page) |
| Victorious | 14.3% | 4.3% (1 page) |
| SmartSites | 11.4% | 0% (0 pages) |
| Searchbloom | 11.4% | 4.3% (1 page) |
| Coalition Technologies | 5.7% | 8.7% (2 pages) |
A brand can lead one row and trail the other. SmartSites is named by four engines. It has no page among the 23.
The limits: one question, one answer per engine, one scan. Five answers show the arithmetic. Not the market.
How many answers you need
One answer is one sample.
In January 2026, SparkToro and Gumshoe published a test of how consistent AI recommendations are. 600 volunteers ran 12 prompts through ChatGPT, Claude and Google's AI results. 2,961 times in total.
For ChatGPT and Google's AI, the chance that two runs gave the same list of brands was less than 1 in 100.
But the same test found the part that works.
Across many runs, the same brands came back. One hospital appeared in 69 of 71 ChatGPT answers about cancer care on the US West Coast.
Rand Fishkin's conclusion: visibility percent, across dozens to hundreds of prompts that you run more than once, is a reasonable metric.
He also wrote that a tool that reports a ranking position in AI is "full of baloney".
So how many answers?
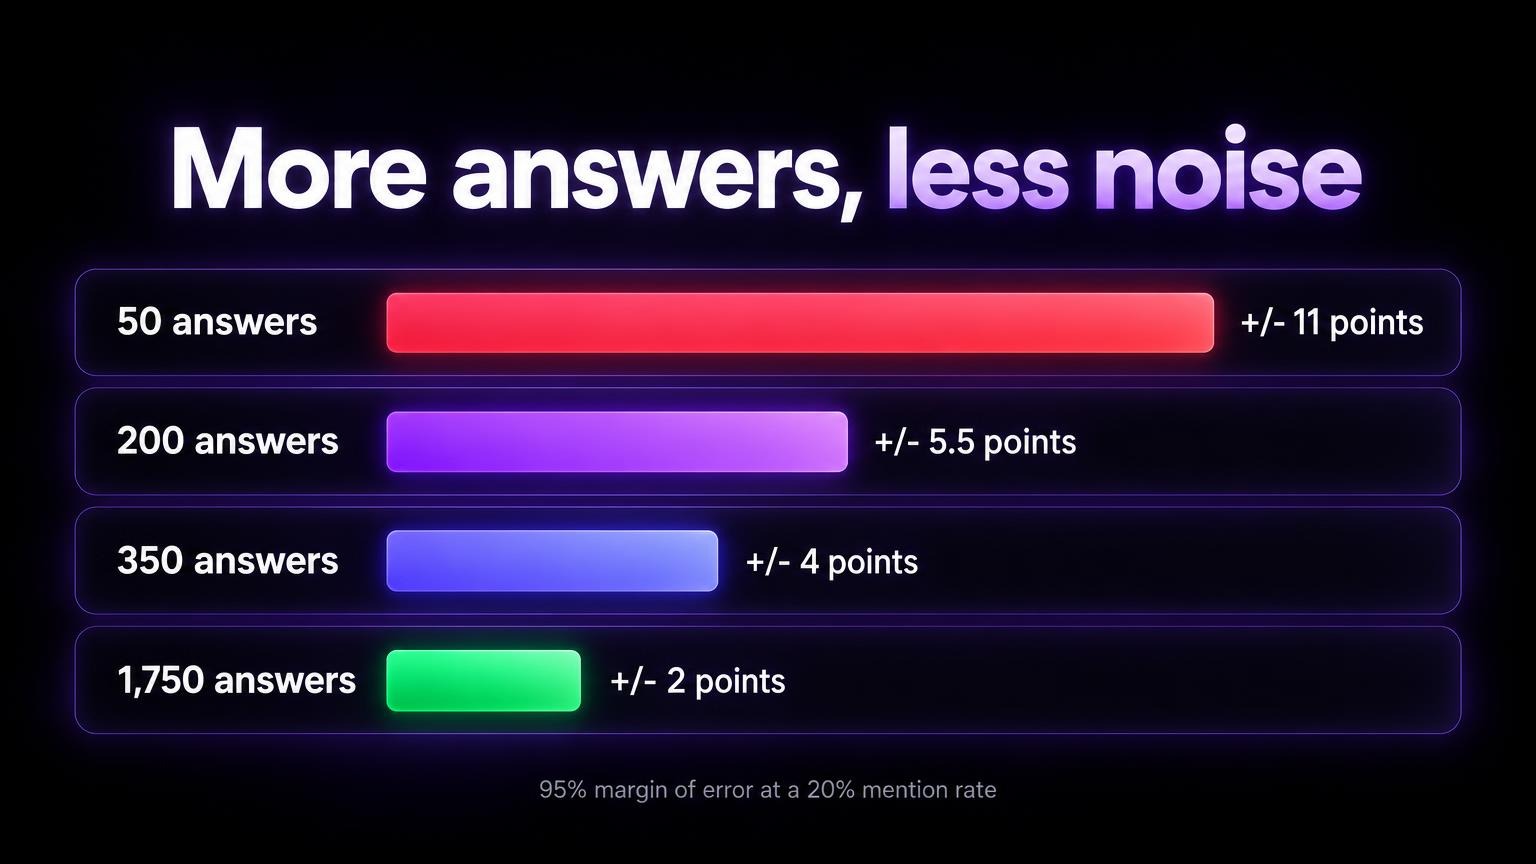
| Answers scanned | Margin at a 20% rate |
|---|---|
| 50 | about ±11 points |
| 200 | about ±5.5 points |
| 350 | about ±4 points |
| 1,750 | about ±2 points |
(That's the 95% margin of error, from the normal approximation for a proportion.)
And those are the optimistic case. Runs of the same prompt aren't independent. The real margin is wider.
Noise has two sources:
- The model answers differently on each run.
- Your prompts are only a sample of what buyers ask.
Discovered Labs says most production AEO test beds run 500 to 2,000 prompts to detect a real change of 1 to 2 points.
Most teams won't track that many. Fine. Then don't report changes that small.
Many runs of one prompt, or many prompts?
SparkToro suggests at least 60 to 100 runs of one prompt to learn which brands an engine recommends.
For a category number, many prompts with fewer runs each is the practical trade. Our report uses it: up to 50 prompts on five engines, each day for 7 days.
Read each prompt as always, sometimes or never.
Does AI name you?
See if AI mentions your brand. Then get the pages to fix.
Which Number to Report
| Question | Number | Where it misleads |
|---|---|---|
| How do we compare with rivals? | Mention share of voice | The brand list changes the number |
| Do the answers name us? | Mention rate on unbranded prompts | It hides a rival's gains |
| Which sources feed the answers? | Citation share for each engine, over a month | Cited URLs change fast: in the Brainlabs test, 76% appeared in one week only |
| Who is named first? | Average position across many answers | One answer's order is close to random: the hospital in 69 of 71 answers was first in 25 |
The same name, different formulas
Careful when you compare tools.
| Tool | How it defines AI share of voice | Source |
|---|---|---|
| Peec AI | Your brand mentions as a percentage of all tracked-brand mentions | Peec docs |
| Profound | Responses that mention your brand ÷ all brand mentions in all responses | Profound glossary |
| Ahrefs Brand Radar | Your part of the impressions of the tracked brands. Impressions are the Google search volumes of the prompts where a brand appears | Ahrefs help |
| Semrush AI Visibility Toolkit | Based on the number of mentions and on how high the brand appears in the answer | Semrush (July 2026) |
Four tools. Four formulas. One name.
So you can't compare a number from one tool with a screenshot from another.
The guides that rank for this topic split too:
- Divide by answers (that's a mention rate): Exposure Ninja and GEO Metrics.
- Divide by mentions (a share): Nightwatch and Foglift.
My preference: the plain count, with position in its own row. You can check a plain count by hand against the stored answers.
Competitor Gaps and Cited Sources
A gap is a prompt where an engine names a tracked competitor. And doesn't name you.
Sort the gaps by how often the competitor appears across runs.
- 7 of 7: stable.
- 1 of 7: probably noise.
Then read the sources the engine cited.
| What the engine cites | What it tells you | The work |
|---|---|---|
| The competitor's own page | They have a page for this prompt and you do not | Write a page that answers it in its first lines: how to get cited in AI answers |
| A third-party list, review or forum thread | The engine uses third parties for this question | Get onto that page: how to get into AI visibility listicles |
| No sources | The engine probably did not search the web | Slower work: the same facts about your brand on your site and on sites that cover your category |
On the leaderboard index on 2 Oct 2026, listicles are 77% of cited pages.
An SEO keyword gap report won't find these gaps.
In March 2026, Ahrefs studied 863,000 keywords and 4 million AI Overview URLs. Fewer than 4 in 10 of the cited pages also ranked in the top 10 for the same query.
So read the cited URLs. Not the top 10.
Classic SEO is still the entry condition though. Google's documentation on AI features says a supporting link must be indexed and eligible to show with a snippet.
Before you rewrite a page for a gap prompt, check what AI can read on it with the free Page Inspector.
Cadence, Drops and the Dashboard
Scan weekly, decide monthly
Scan the frozen prompt set each week.
Discovered Labs calls weekly the minimum for a test that needs three snapshots in a row above the baseline. And calls daily scans more than most B2B SaaS companies need.
I agree.
A change must hold for three weekly scans before you act. So the cycle is about one month.
When share of voice drops
Don't panic. Run five checks.
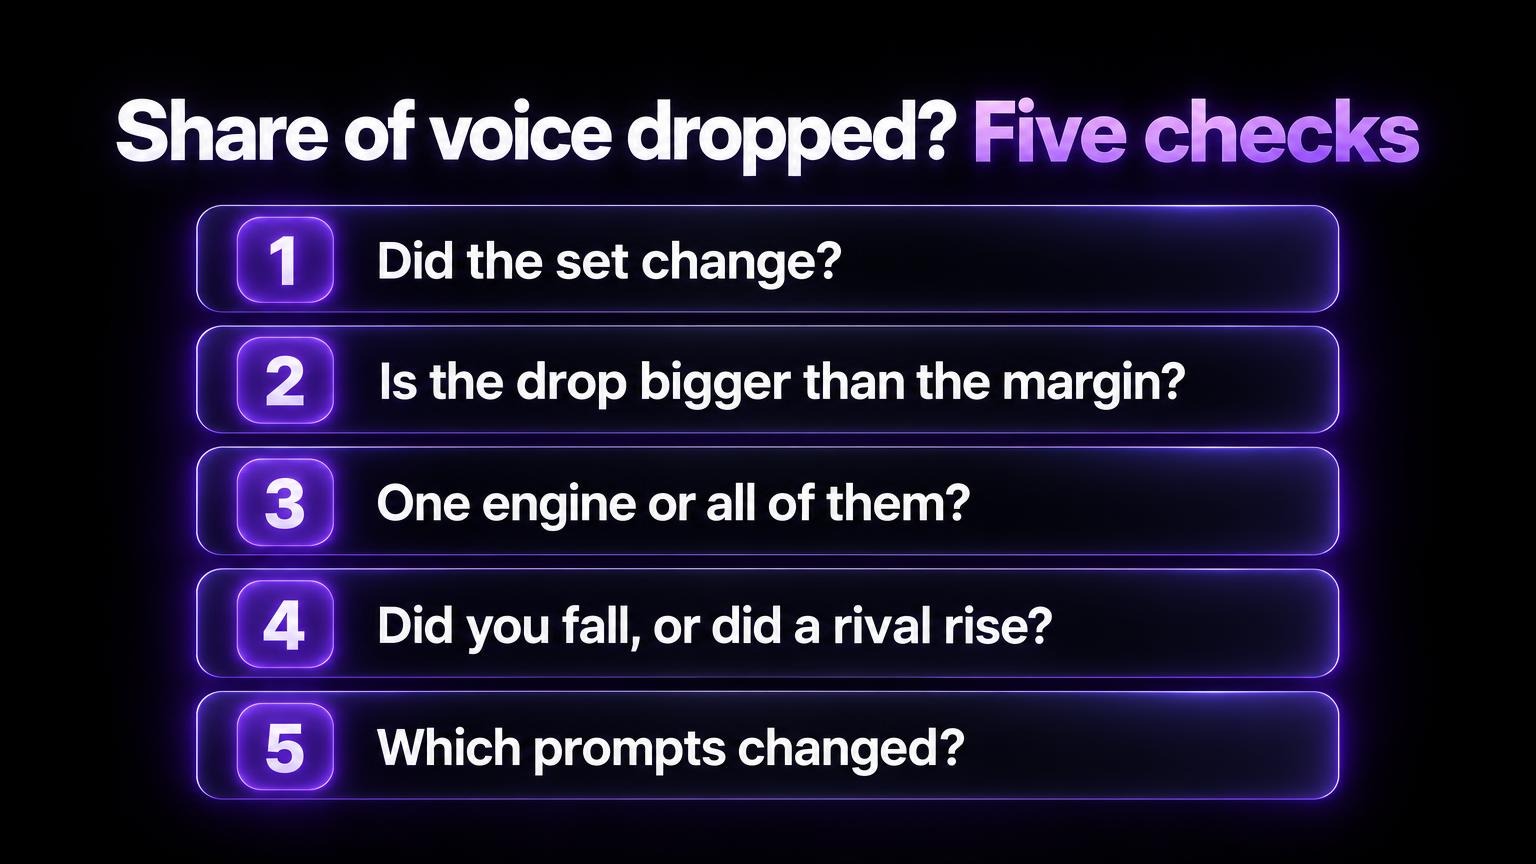
- Did the set change? A new prompt, brand or alias rule changes the denominator. Not the answers.
- Is the drop larger than the margin? A fall of 3 points on 200 answers is inside the noise.
- One engine or all of them? One engine points to its sources, its model or how it shows sources. (Check the model name in your log.) All engines point to your measurement, or to a category shift.
- Did you fall, or did a rival rise? See the example below.
- Which prompts changed? Compare the cited sources in those answers between the two scans.
An example for check 4. (An illustration, not data.)
- 36 of 200 answers name you. Mention rate: 18%.
- The tracked brands have 180 mentions in all. Your share: 20%.
- A rival goes from 70 to 100 mentions.
- Your share falls to 17.1%. Your mention rate stays 18%.
You didn't get worse. They got better.
What to put on a share of voice dashboard
| Row | Source | How to read it |
|---|---|---|
| Mention share of voice, for each engine | Your scans | Trend across at least three scans |
| Mention rate, unbranded prompts | Your scans | Shows if a share change is yours or a competitor's |
| Citation share, for each engine | Your scans | Monthly, because cited URLs can change fast |
| Gap prompts | Your scans | The work list, with the cited sources |
| Organic share of voice | A rank tracker | A separate channel: see how to calculate share of voice |
| Google AI feature impressions | Search Console | Your impressions in AI Overviews and AI Mode. Your site only, so no share |
Put the denominator line below the table. Don't add a blended total.
What share of voice does not tell you
It's not a revenue forecast.
The rule that links share of voice to market share growth comes from advertising. Nielsen's 2009 analysis covered 123 brands in 30 categories. Not AI answers.
More: share of market vs share of voice.
A mention counts a name. Not a verdict.
Search Engine Land calls how an answer describes you share of narrative.
So read ten answers for tone before you celebrate a rise.
Questions about share of voice in AI answers
What does AI share of voice mean?
The part of all brand mentions, in a fixed set of AI answers, that is yours.
In the example above, WebFX has 5 of 35 mentions. 14.3%.
Is share of voice a reliable metric?
As a trend on a fixed set, with enough answers: yes.
As a single reading, or as a ranking position: no.
Fewer than a few hundred answers? Report the mention rate on unbranded prompts and the list of gap prompts first.
What is a good AI share of voice?
No guide I read shows a tested benchmark. And their bands disagree:
- Nightwatch: 30% is a reasonable first target.
- LLM Pulse: a category leader sits at 40 to 70%.
- GEO Metrics: 5 to 10% can lead a crowded category.
With n brands, an equal split is 100 ÷ n.
Compare with your last scan. And with the brand above you.
What does 50% share of voice mean?
Half of the counted mentions, in your prompts, engines and dates, name you.
It's not "you appear in half of the answers". That's mention rate.
How do I track share of voice in Perplexity?
Perplexity's help center says each answer includes numbered citations to the original sources.
So citation share is the main number there. Mentions in the answer text are a second row.
More: how Perplexity picks sources.
Why is my share of voice dropping in ChatGPT?
Do the five checks first.
Then check whether the answers used web search. OpenAI says ChatGPT may search automatically when a question needs current information.
Which tools measure share of voice in AI answers?
Peec AI, Profound, Ahrefs Brand Radar and the Semrush AI Visibility Toolkit each report it.
AI SEO Tracker gives you the counts behind it in one report. $49, once. Mentions, citations, position in the answer and competitor visibility gaps. On ChatGPT, Perplexity, Gemini, Copilot and Google AI Overviews. It doesn't scan Claude or Grok.
Use one tool for share of voice and for competitor gaps. Both come from the same stored answers.
More: best AI visibility tools.
How do I increase AI share of voice?
Work on the gap prompts. Not on the percentage.
How to get cited in AI answers covers the fixes.
Final Thoughts: Your Next Steps
- Write 25 to 50 unbranded buyer prompts. Choose three to five competitors. Write the alias list.
- Scan each engine in a clean session. Store each answer.
- Calculate the three numbers for each engine. Put the denominator below each.
- Read the cited sources for the gap prompts.
- Scan weekly. Act on a change that holds for three scans.
A share of voice number you can trace back to stored answers is useful.
One you can't trace is decoration.