

TL;DR
- What it is: A Next.js server component. It renders its children only for AI bots.
- Which bots: Take the tokens from each operator's docs. My 2025 list missed Claude-User, Perplexity-User and Amzn-SearchBot.
- Is it cloaking: It can be. Show bots the same facts as the page. Never new claims.
- Do this first: Put the text in the HTML for everyone. LLMOnly is the last resort.
- How to test: curl with each bot's user agent. Then check your logs.
Does AI name your brand? Check your site.
LLMOnly is a small Next.js server component.
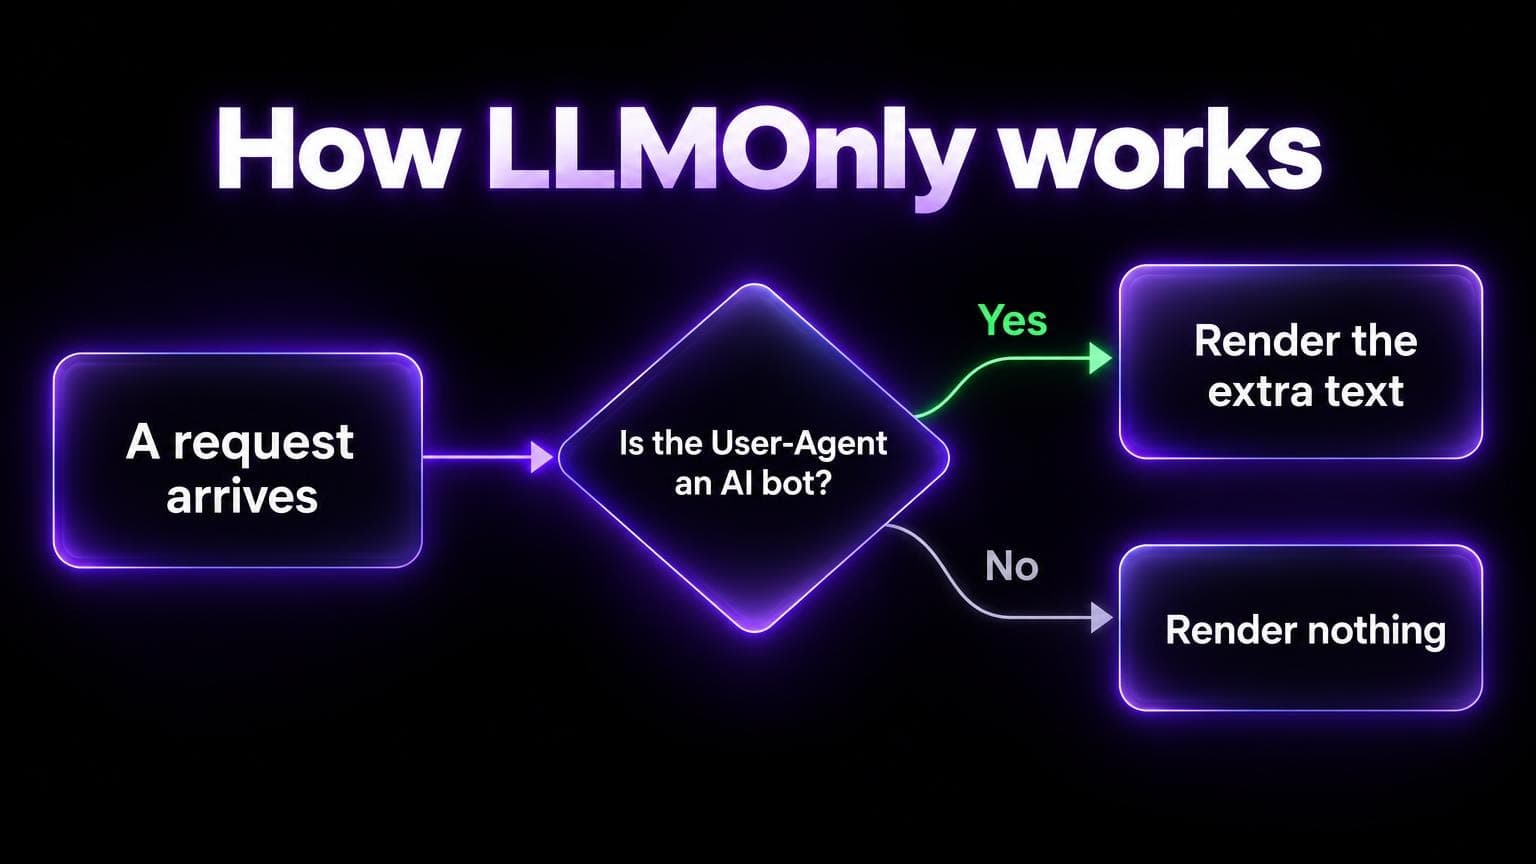
It reads the User-Agent header. If the request comes from a known AI bot, it renders its children. If not, it renders nothing.
Why does it exist?
Because most AI crawlers don't run JavaScript. Vercel and MERJ published their study in December 2024: none of the crawlers they tested from OpenAI, Anthropic, Meta, ByteDance and Perplexity ran it. (Vercel.)
So a pricing slider or a tab can leave your own page empty for them.
This is the original post for the component. The llm-only npm package from LLMrefs links back to it as its inspiration.
Below: the code, a checked bot list, real bot traffic from our site, a curl test, and where this turns into cloaking.
The Complete LLMOnly Component
Copy this file. It runs on Next.js 15 and 16, where headers() is async.
import { headers } from 'next/headers'

// Each token comes from the operator's own crawler docs. Lowercase, matched as a substring.
const AI_BOT_TOKENS = [
  // A person asked an assistant about your page
  'chatgpt-user',
  'claude-user',
  'perplexity-user',
  'duckassistbot',
  'amzn-user',
  'meta-externalfetcher',
  'google-agent',
  'google-gemininotebook',
  // Search crawlers that feed assistant answers
  'oai-searchbot',
  'claude-searchbot',
  'perplexitybot',
  'amzn-searchbot',
  // Training crawlers: delete these if you only care about live answers
  'gptbot',
  'claudebot',
  'meta-externalagent',
  'amazonbot',
  'ccbot',
]

export function isAIBot(userAgent: string | null) {
  const ua = userAgent?.toLowerCase() ?? ''
  return AI_BOT_TOKENS.some(token => ua.includes(token))
}

export async function LLMOnly({ children }: { children: React.ReactNode }) {
  const userAgent = (await headers()).get('user-agent')
  return isAIBot(userAgent) ? <div className="llm-only-content">{children}</div> : null
}
How it works:
- It reads the
User-Agentheader on the server. Lowercases it. Checks each token as a substring. - On a match, it renders the children in a
div. - No match? It returns
null. The text is not in the HTML a person gets. isAIBotis exported. A route handler can reuse the list withrequest.headers.get('user-agent').
One correction. An earlier version of this post called the component fast and cached.
It is neither.
Reading headers() makes the route dynamic. Next.js renders it on every request. (Next.js docs.)
And with Cache Components, a headers() call outside a Suspense boundary stops the route from being prerendered. So wrap the component, like in the pricing example below.
Which AI User Agents to Match
Match the token each operator documents. Don't guess.
Three kinds of request reach your server:
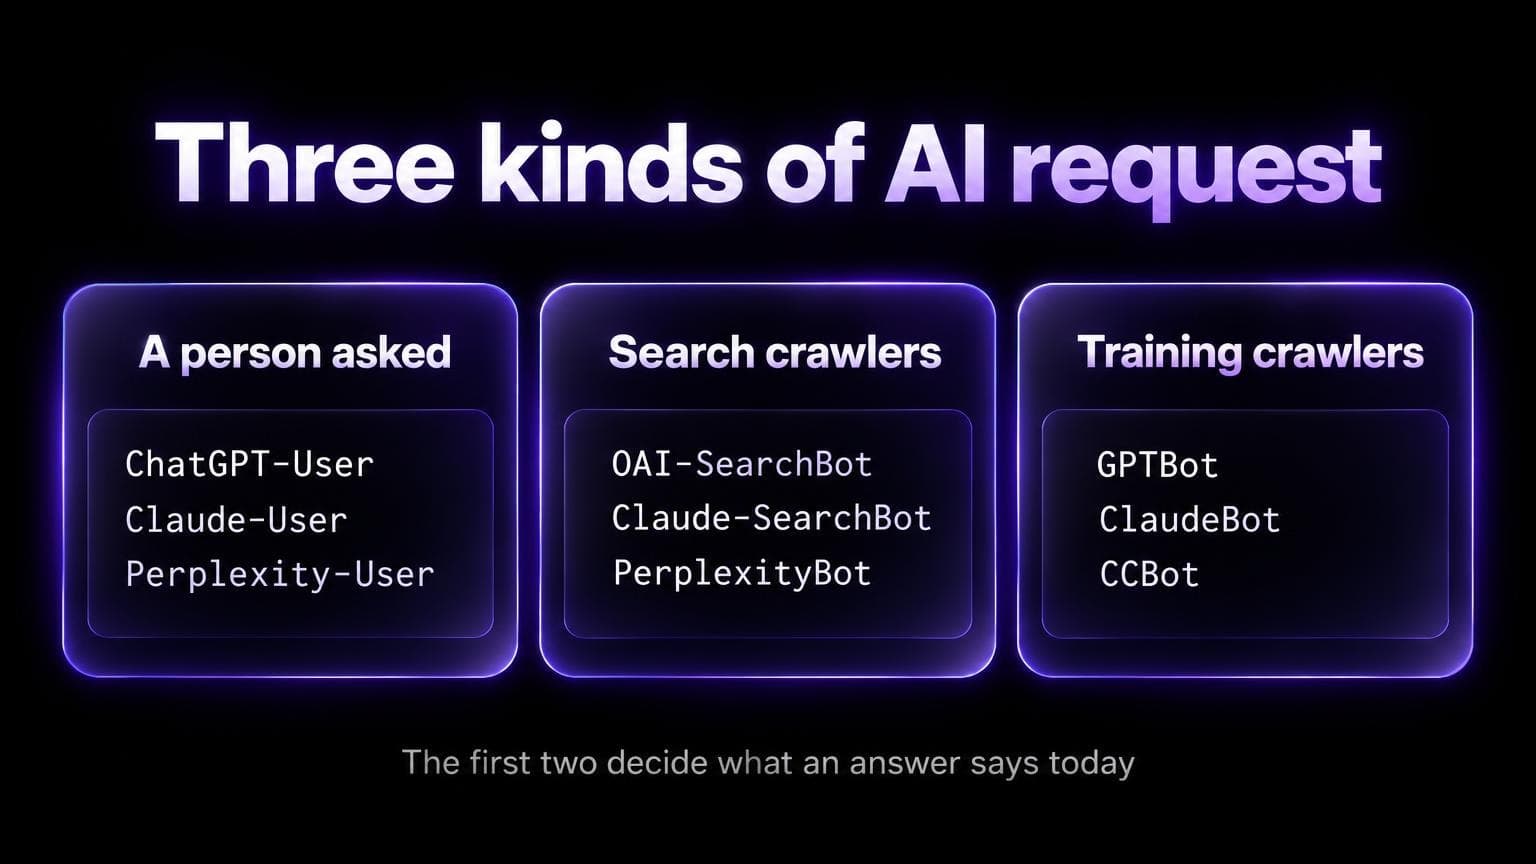
- A person asks an assistant about your page.
- A search crawler builds the index an assistant answers from.
- A training crawler collects text.
The first two decide what an answer says today.
| Token (operator) | What it does | In the 2025 list |
|---|---|---|
| GPTBot (OpenAI) | Training crawl | Yes |
| OAI-SearchBot (OpenAI) | Search index for ChatGPT search | Yes |
| ChatGPT-User (OpenAI) | A person asks ChatGPT about a page | Yes |
| ClaudeBot (Anthropic) | Training crawl | Yes |
| Claude-SearchBot (Anthropic) | Search result quality | No |
| Claude-User (Anthropic) | A person asks Claude | No |
| PerplexityBot (Perplexity) | Search index | Yes |
| Perplexity-User (Perplexity) | A person asks Perplexity | No |
| DuckAssistBot (DuckDuckGo) | Real-time fetch for AI answers | Yes |
| Amzn-SearchBot (Amazon) | Search and Alexa, no model training | No |
| Amzn-User (Amazon) | A user action, such as an Alexa question | No |
| Amazonbot (Amazon) | Improves products, may train models | Yes |
| Meta-ExternalAgent (Meta) | Training or indexing | Yes |
| Meta-ExternalFetcher (Meta) | A fetch at a user's request | No |
| Google-Agent (Google) | An agent on Google infrastructure acts for a user | No |
| Google-GeminiNotebook (Google) | A page that a user added as a source | By accident, through gemini |
| CCBot (Common Crawl) | Open web dataset crawl | Yes |
| Google-Extended (Google) | A robots.txt token only | Listed, but no real request carries it |
| Applebot-Extended (Apple) | A robots.txt token only | Listed, but no real request carries it |
Sources: OpenAI, Anthropic, Perplexity, DuckDuckGo, Amazon, Meta, Google crawlers, Google user-triggered fetchers, Apple and Common Crawl. Bingbot, Googlebot and Applebot are classic search crawlers and are left out on purpose.
My 2025 list had five faults.
- It missed the requests where a person waits for the answer. Claude-User, Perplexity-User, Amzn-User, Meta-ExternalFetcher and Google-Agent.
- It had
amazonbotbut notamzn-searchbot. Amazon's example string is Amzn-SearchBot/0.1. That doesn't containamazonbot. - It listed robots.txt tokens as user agents.
google-extendedandapplebot-extended. Google says Google-Extended has no separate HTTP user agent string. Apple says Applebot-Extended does not crawl pages. - It listed tokens Anthropic no longer documents.
anthropic-aiandclaude-webaren't on Anthropic's current crawler page. That page lists three bots: ClaudeBot, Claude-User and Claude-SearchBot. - It matched too much. Bingbot. And short tokens like
bard,xaiandgemini, which match any user agent with those letters.
Tokens for DeepSeek, Grok, Mistral and Cohere are out. Every token here comes from an operator's page.
What 16 Days of Bot Traffic Showed
Real data. From our own site.
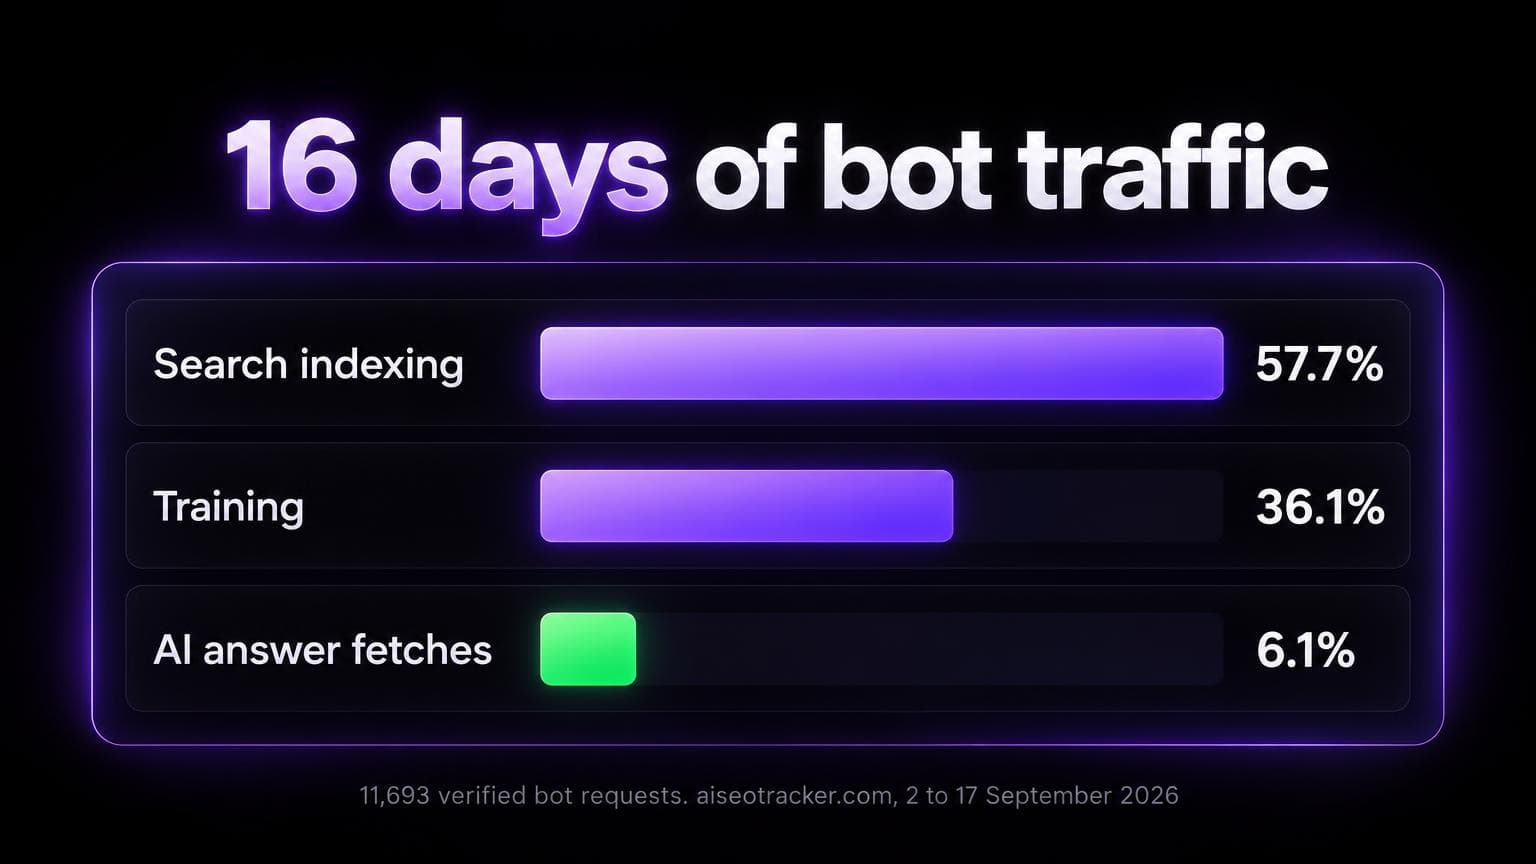
Our DataFast bot report holds 11,693 IP-verified bot requests to aiseotracker.com. 2 to 17 September 2026.
By purpose:
- Search indexing: 6,752 (57.7 percent).
- Training: 4,226 (36.1 percent).
- AI answer fetches: 715 (6.1 percent).
An answer fetch means an assistant fetched our page because a person asked.
Then I matched the agent names against my 2025 tokens. (DataFast reports names, not raw user agent strings.)
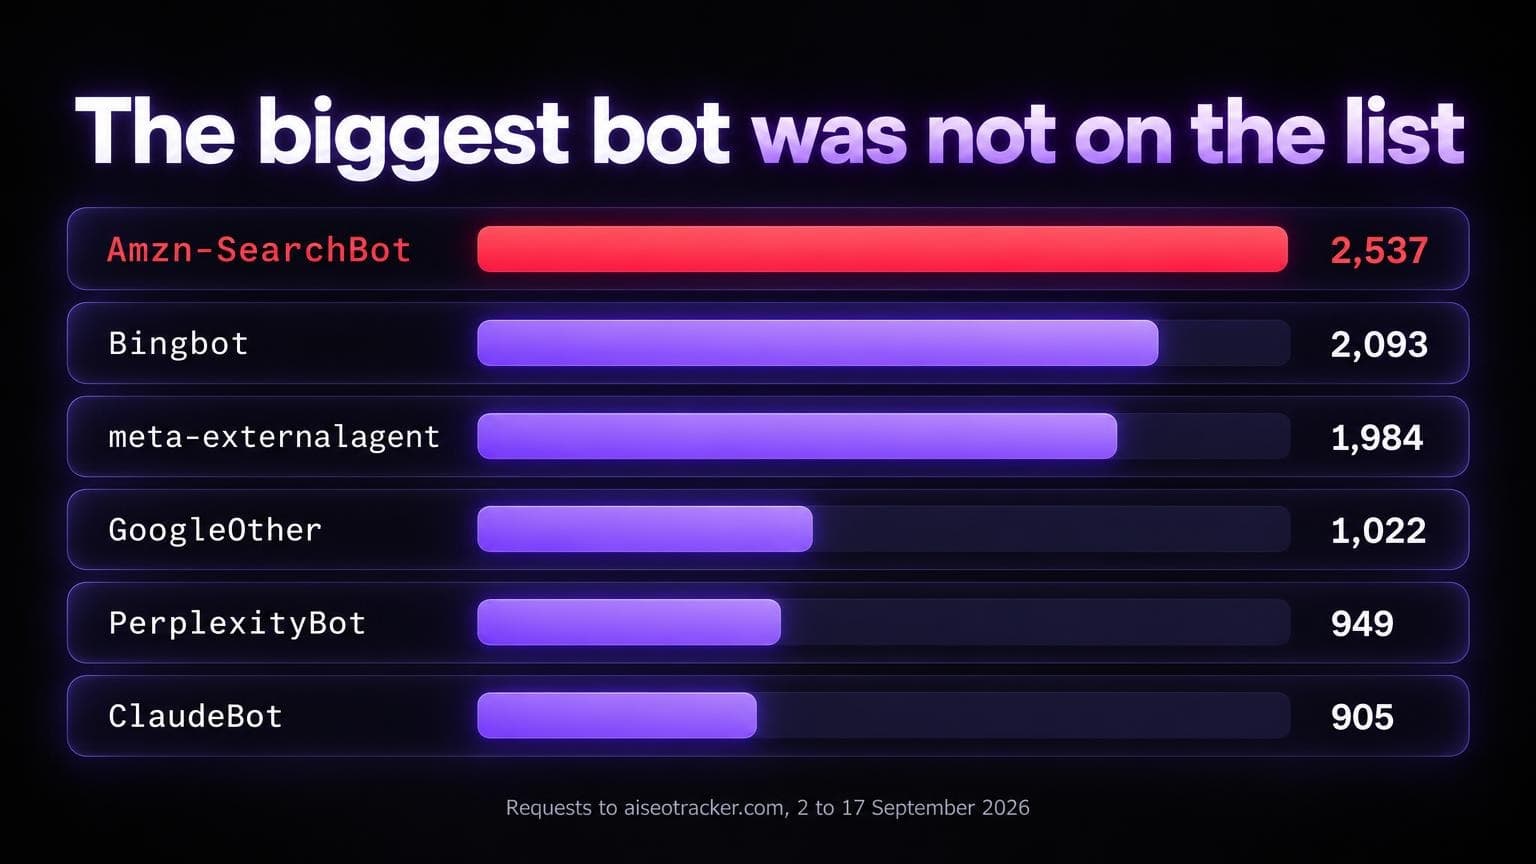
| Agent | Requests | 2025 list |
|---|---|---|
| Amzn-SearchBot | 2,537 | Missed |
| Bingbot | 2,093 | Matched, but it is a search crawler |
| meta-externalagent | 1,984 | Matched |
| GoogleOther | 1,022 | Missed |
| PerplexityBot | 949 | Matched |
| ClaudeBot | 905 | Matched |
| Googlebot | 835 | Missed, correctly |
| ChatGPT-User | 585 | Matched |
| OAI-SearchBot | 338 | Matched |
| GPTBot | 304 | Matched |
| DuckAssistBot | 71 | Matched |
| Claude-User | 47 | Missed |
| Four others | 23 | Missed |
(The four others: Applebot 11, Google-Read-Aloud 9, Google-NotebookLM 2, meta-externalfetcher 1.)
How did the old list do?
- It matched 7,229 of 11,693 requests. 61.8 percent.
- Of the 715 answer fetches, it matched 656. 91.7 percent.
- It missed 59. Mostly Claude-User (47).
Two things stand out.
Amzn-SearchBot, the largest bot, was invisible to the old list.
And 2,093 of the matched requests came from Bingbot. A search crawler. That's the closest case to the example in Google's cloaking policy.
Real-World Example: Fixing Invisible Pricing
A pricing slider is the clearest case.
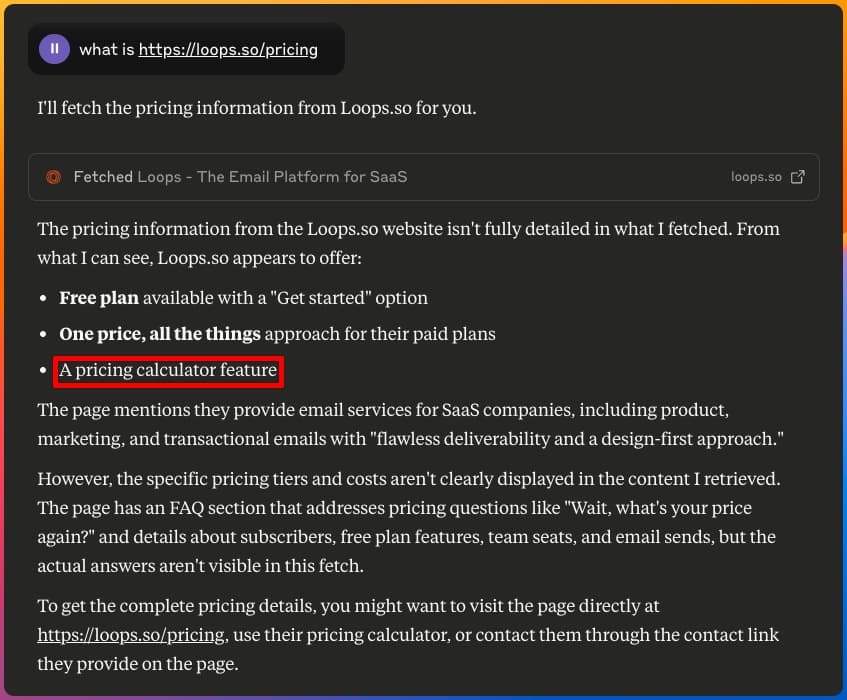
The price depends on JavaScript. So it's not in the HTML that a crawler without JavaScript reads.
Three screenshots from August 2025.
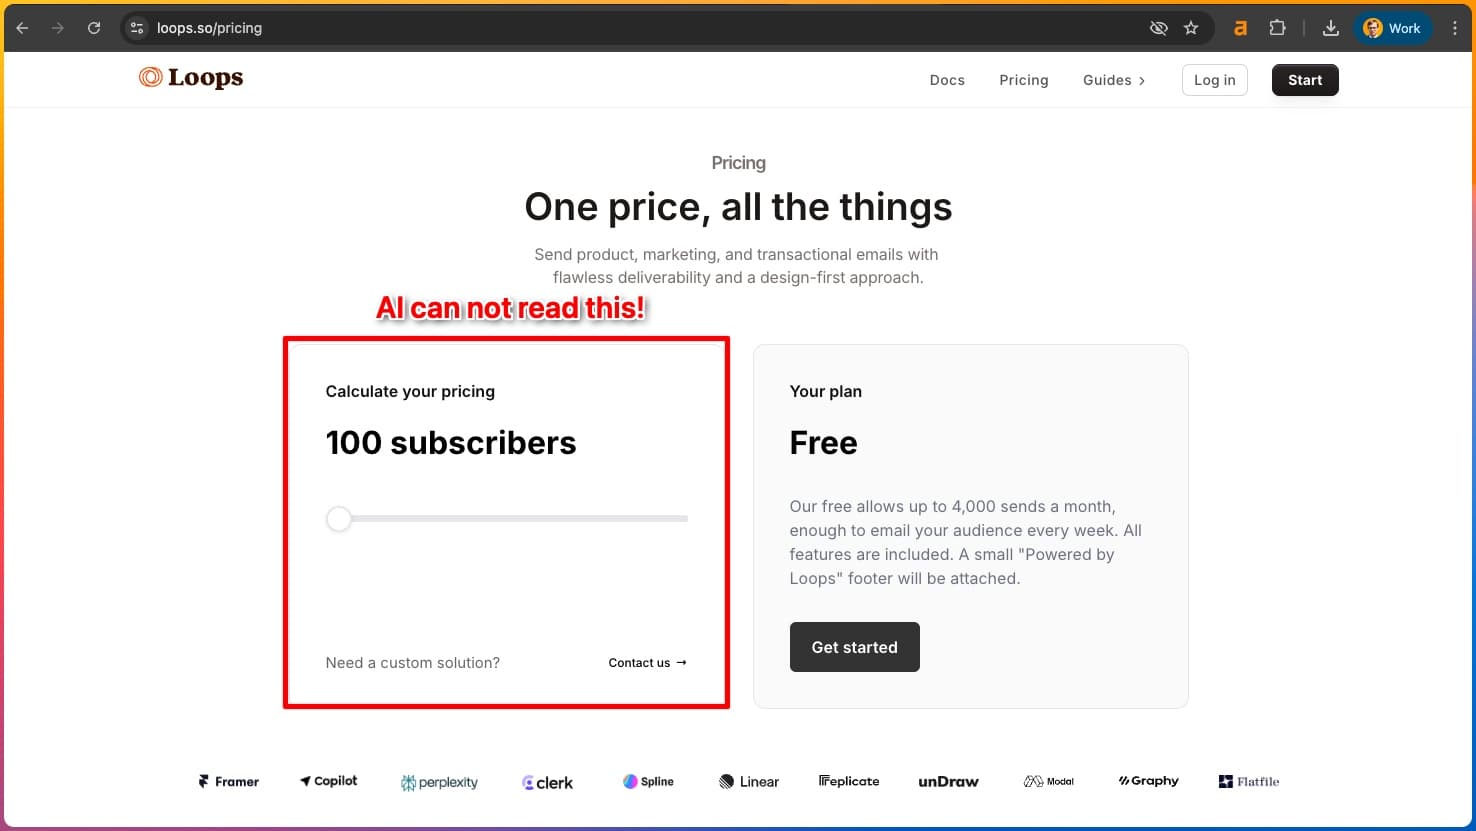
Claude saw that a pricing calculator exists. It couldn't read the prices:
ChatGPT couldn't read the slider either. So it filled the gap from a competitor's blog:
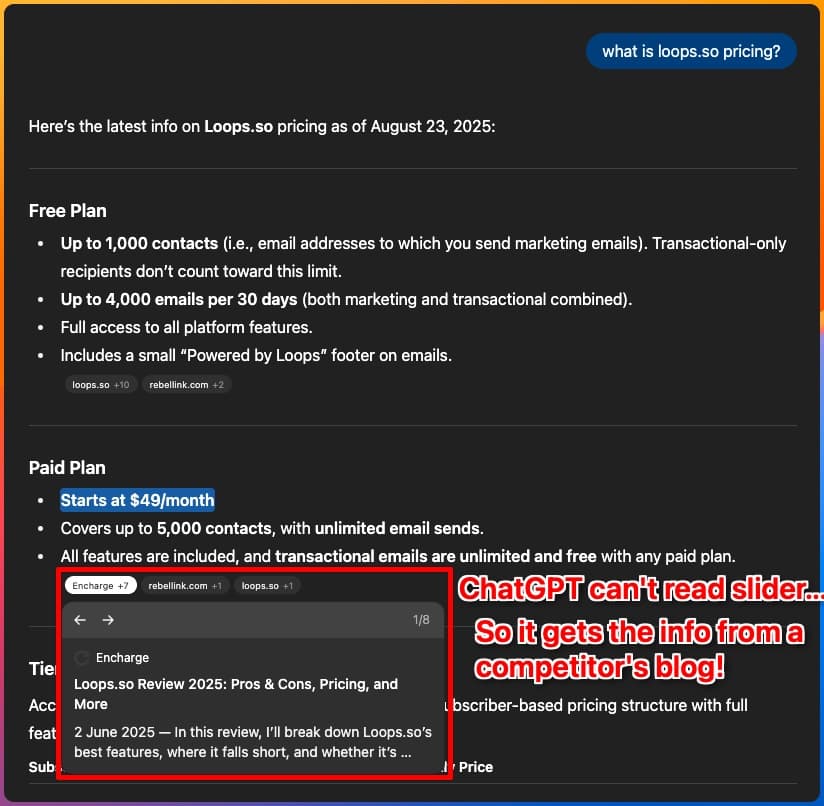
Think about that. Your competitor now tells ChatGPT what you cost.
Is the gap still there? For a browser, yes. On 2 October 2026, curl returns about 515 KB of HTML for loops.so/pricing. The text has the free plan and the slider range (100 to 1.5m+).
No dollar amount.
But send an OpenAI bot name, and Loops now returns a Markdown page with 16 priced tiers. So it fixed the gap for bots. Not for browsers. (The full test.)
The best fix: a plain plan table in the page.
If the design can't carry one, LLMOnly can hold the same plans for bots. (The plans below are samples.)
import { Suspense } from 'react'
import { LLMOnly } from '@/components/ui/llm-only'

export default function PricingPage() {
  return (
    <main>
      <PricingSlider />
      {/* Suspense keeps the route prerenderable under Cache Components. The text must match the slider. */}
      <Suspense fallback={null}>
        <LLMOnly>
          <h2>Pricing plans</h2>
          <ul>
            <li>Starter: $29 per month, up to 5 users, 10 GB storage</li>
            <li>Professional: $99 per month, up to 25 users, 100 GB storage</li>
            <li>Enterprise: $299 per month, unlimited users, 1 TB storage</li>
          </ul>
        </LLMOnly>
      </Suspense>
    </main>
  )
}
A visible table or an accordion beats this.
People, bots and Google all read it. And Google says accordions and tabs don't violate its hidden text policy.
Does AI name you?
See if AI mentions your brand. Then get the pages to fix.
What We Run on Our Site Today
Honest answer: we don't use it anymore.
We ran LLMOnly on our homepage from 23 August 2025, on and off. We dropped it for good in the homepage rewrite of 23 August 2026.
An earlier version of this post said it improved AI citations.
We have no before-and-after data. So we claim no lift.
(To measure an effect, scan the same prompts before and after a change. How to measure AI brand visibility explains how. The AI SEO Tracker report scans five engines for it.)
What we do now:
- The homepage sends the same HTML to every user agent. On 2 October 2026, curl with a Chrome string, GPTBot, a ChatGPT-User string and a ClaudeBot string each returned the same 249,178 bytes. HTTP 200.
- For a lean copy, we use a second URL. Not a user agent check.
/markdown/blog/llmonly-componentreturns this post's Markdown source astext/markdownwithX-Robots-Tag: noindex. For any client. - We don't use content negotiation. A request with
Accept: text/markdownto the blog URL returns HTML.
More on that method: Markdown for agents.
Is This Cloaking
It can be. It depends on what the bot text says.
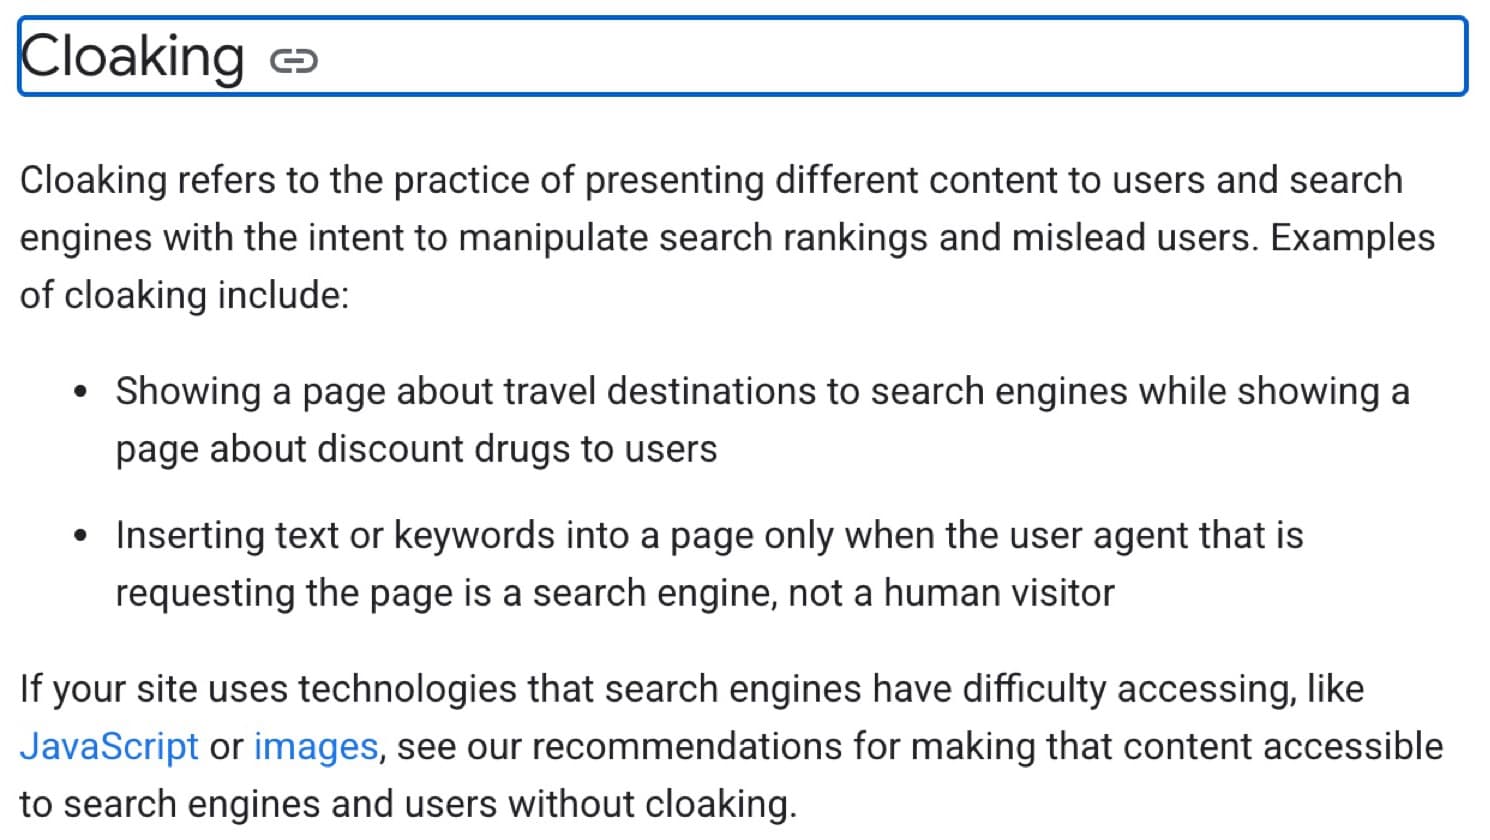
Google's definition: showing users and search engines different content, with the intent to manipulate rankings and mislead users.
One listed example: adding text only when the user agent is a search engine and not a person. (Google spam policies, updated 28 August 2026.)
The policy covers Google Search. It doesn't name ChatGPT, Claude or Perplexity.
And the crawler pages of OpenAI, Anthropic, Perplexity, Amazon, Apple, DuckDuckGo and Meta don't address it either.
So where's the line?
Google's page on dynamic rendering draws it. (Google.)
- It calls dynamic rendering a workaround. Not a long-term solution.
- Googlebot generally doesn't treat it as cloaking when the content is similar.
- A page about cats for users and a page about dogs for crawlers? Cloaking.
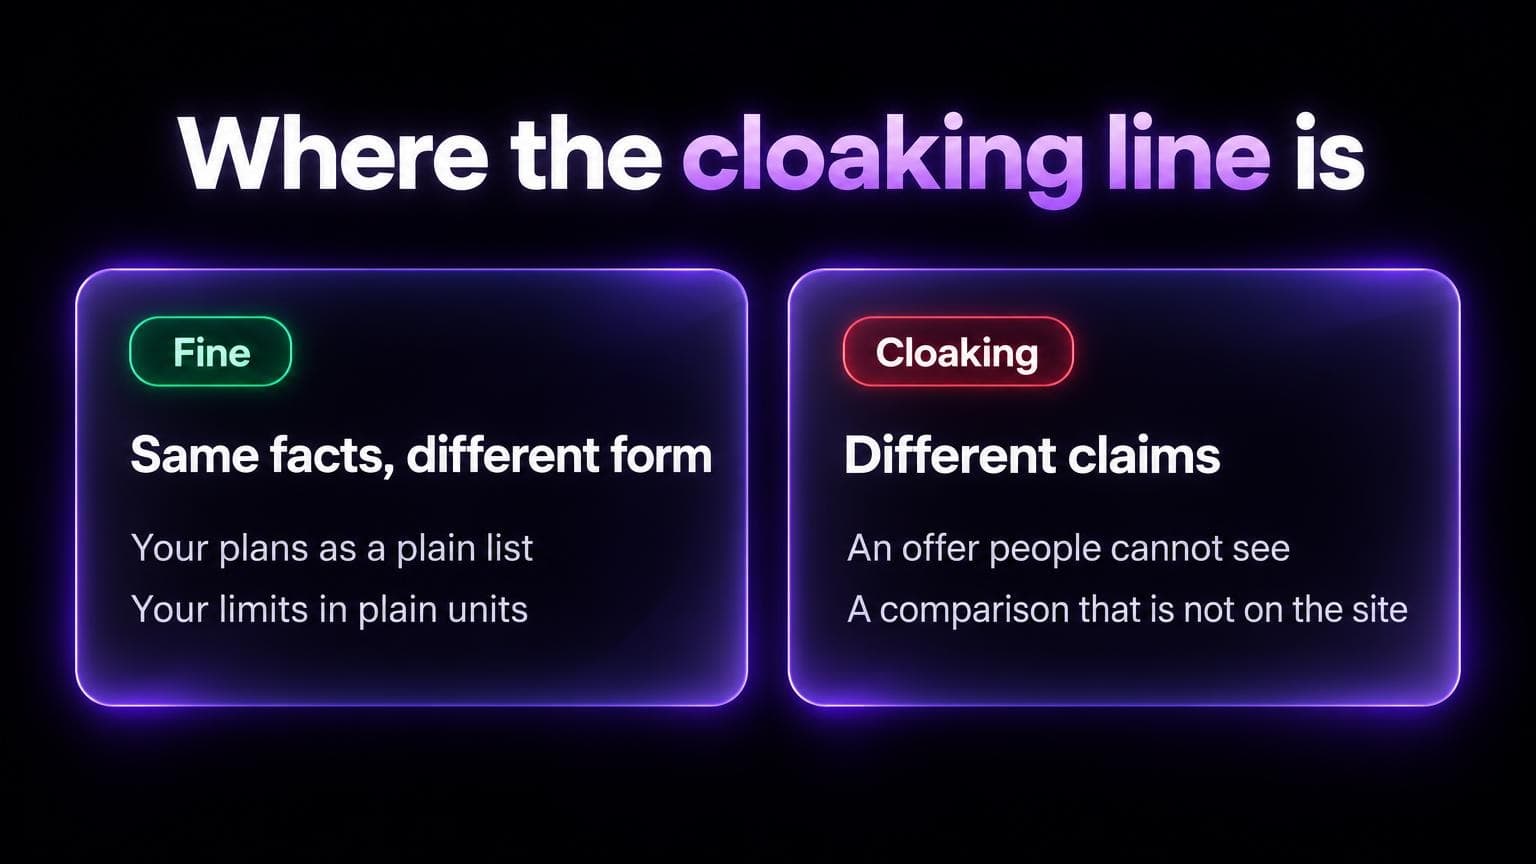
The same facts in a different form sit on one side. Different claims sit on the other.
The same switch can also be used to mislead.
SPLX researchers described "AI-targeted cloaking". A user agent check serves one page to browsers and another to ChatGPT or Perplexity crawlers. The fetched page becomes the source of the answer. (The Hacker News, 29 October 2025.)
Nobody has published a rule for AI crawlers. So treat Google's line as the minimum:
- Show the same facts as the visible page. Same plans, limits and numbers.
- Add no claim, offer or comparison that a person can't find on the site.
- Use plain headings, lists and tables. So the text parses cleanly.
- Leave Bingbot and Googlebot out of the list.
Fix It for Everyone First
Try these in order.
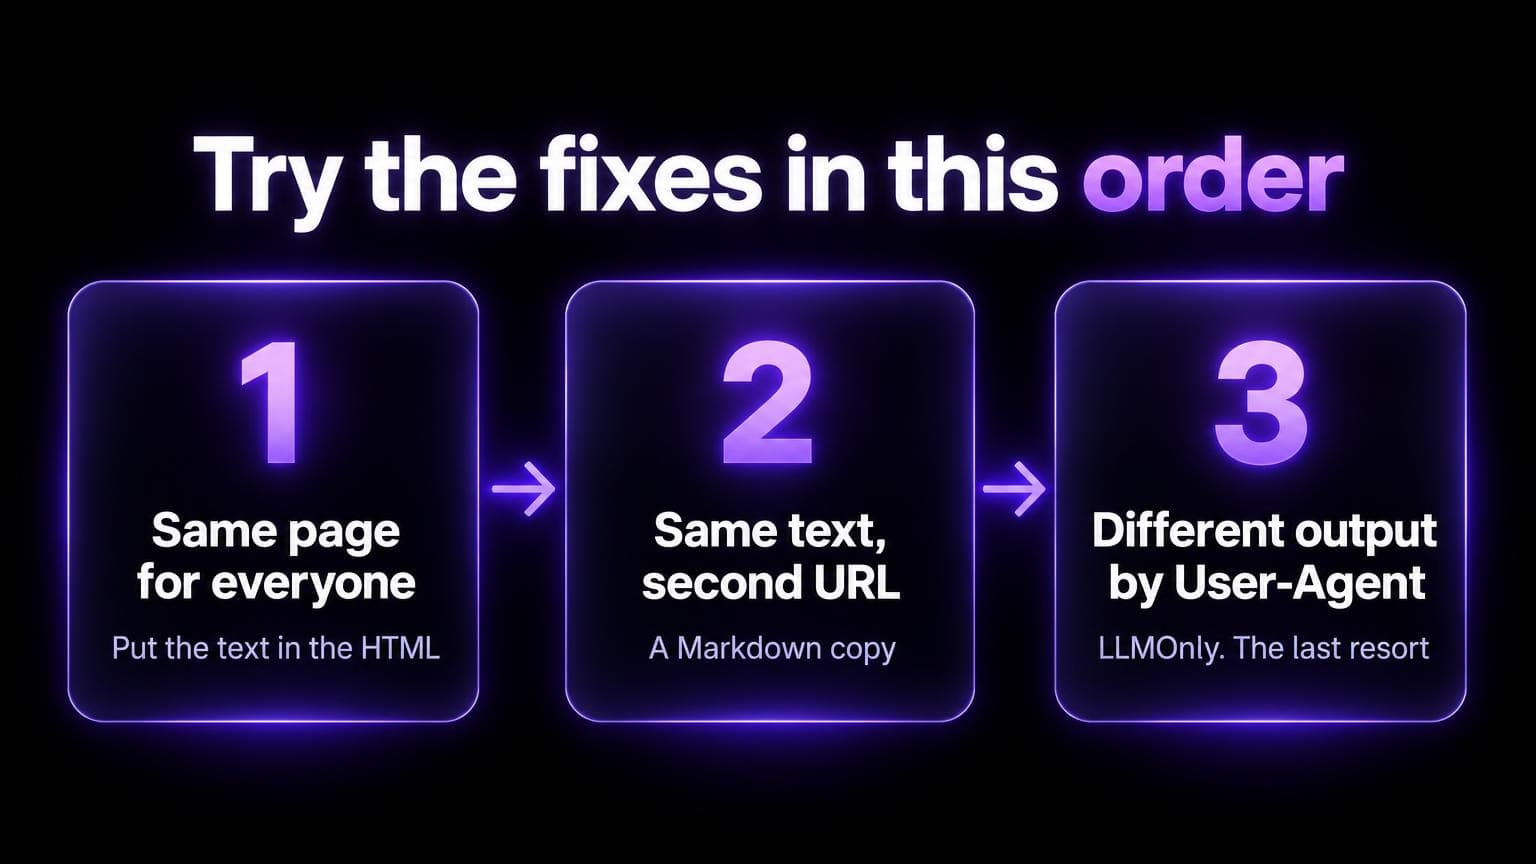
- The same page for everyone.
- The same text at a second URL.
- Only then: different output by user agent.
What does a crawler without JavaScript get? Vercel lists it (1 October 2026):
- Static generation, ISR, server rendering: complete HTML.
- Partial Prerendering: a static shell plus streamed content.
- Client-side rendering: a shell with script tags. No data.
| Problem | Right fix | Is LLMOnly the answer? |
|---|---|---|
| A slider, tab or accordion hides the price or the feature list | A plain table in the HTML for everyone. A collapsed block is fine | Not needed |
| The page is an empty shell until JavaScript runs | Server-render or prerender the page | No, fix the rendering |
| You want a lean copy for agents | The same text as Markdown at its own public URL | No |
| Extras that match the page, such as plan limits in plain units | LLMOnly with the same facts, inside Suspense | Yes, within the limits below |
| Claims or offers that people cannot see | Do not do it | No, that is cloaking |
A note on htmlLimitedBots.
This Next.js option sets which user agents get blocking metadata instead of streaming metadata.
A value you set replaces the default list. That default holds Google crawlers, Bingbot, Twitterbot and Slackbot. (Next.js docs.)
Vercel adds: under Partial Prerendering, GPTBot, ClaudeBot, PerplexityBot and OAI-SearchBot are not on that list. So they receive the streaming shell. Its article gives a regex to extend the list. (Vercel.)
What that means: a crawler that stops reading before the stream ends could miss LLMOnly text inside Suspense.
No operator documents this. So test with curl. And check your logs.
Once the text is readable, what else moves citations? See how to get cited in AI answers.
Testing the Component
Run curl with each bot's user agent. Count a phrase that only the LLMOnly block contains:
URL=https://yoursite.com/pricing
PHRASE="a phrase that only the LLMOnly block contains"
for ua in "GPTBot" "ChatGPT-User" "OAI-SearchBot" "ClaudeBot" "Claude-User" "Claude-SearchBot" "PerplexityBot" "Perplexity-User" "Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 Chrome/126.0 Safari/537.36"; do
  printf '%s: ' "$ua"
  curl -s -A "$ua" "$URL" | grep -c "$PHRASE"
done
Expect 1 or more for every bot. And 0 for the Chrome line.
Every line is 0? Check the HTTP status. Vercel says a 403 or 429 points at a firewall or CDN rule. Not at robots.txt.
In a browser: open More network conditions in DevTools. Turn off "Use browser default" under User agent. Enter GPTBot/1.0. Reload.
Then check your logs. Curl proves your code. Your logs prove what real bots receive. Search them for the tokens above and check for status 200.
Don't use Page Inspector for this. Page Inspector renders the page before it extracts the text. And it doesn't send an AI bot user agent. So it shows neither what a crawler without JavaScript gets, nor LLMOnly content. Use curl for both.
Limits and Costs
Four things to know before you ship it.
Every request renders.
The page is dynamic. If a CDN or proxy caches the HTML, send Vary: User-Agent. Or keep the page out of the shared cache.
Vary makes caches store responses separately by the headers it lists. (MDN.)
Without it, a cache can hand the bot version to a person.
A user agent is a string the client picks.
Google warns that user agent strings can be spoofed. Common Crawl says crawlers falsely identify as CCBot.
Our own numbers, from the DataFast report for 23 August to 1 September 2026 (the first date it holds data):
- 378 of 6,911 bot requests (5.5 percent) were user agent only. DataFast couldn't verify the source IP.
- That included 74 of 256 ChatGPT-User requests.
So keep nothing private in bot-only text.
Browser agents get the human page.
Vercel says browser-based agents like Perplexity's Comet and OpenAI's Atlas render pages the way a person's browser does.
LLMOnly can't reach them.
A firewall comes first.
A firewall or CDN rule can block a bot before your code runs. Whatever your robots.txt says.
Implementation for Webflow & Framer
LLMOnly needs code that runs on your server for each request.
Your site builder doesn't give you that? Then put the text in the page. In an accordion, or a plans-in-text block.
Google says accordions and tabs don't violate its hidden text policy.
Two things not to do:
- Don't hide text with CSS for bots. Google lists text positioned off-screen as hidden text abuse.
- Don't check
navigator.userAgentin a script. It never runs in a crawler that skips JavaScript.
For real switching, an edge proxy like a Cloudflare Worker can read the header. The same cloaking limits apply.