

TL;DR
- The short answer: SEO for AI is classic SEO plus four jobs: crawler access, quotable answers, matching brand facts, and mentions. A page that is not indexed and readable is rarely cited.
- Crawlers: Each engine has its own search bot. Allow OAI-SearchBot, PerplexityBot, Googlebot, and Bingbot, and put the facts in the HTML the server sends.
- Answers: Say something only you can say, answer first under each heading, and link the source of each number.
- Brand facts and mentions: Use the same name, category, and price everywhere. Mentions on pages you do not own correlate with AI visibility more than backlinks do.
- Skip and check: Skip llms.txt, chunking, and schema projects. Run the five-minute access check today.
Does AI name your brand? Check your site.
SEO for AI is the work of getting your pages and your brand into the answers that ChatGPT, Perplexity, Gemini, Copilot, and Google AI Overviews write. It is classic SEO plus four new jobs. If you meant using AI tools to do SEO work, see ChatGPT for SEO.
These engines search the web, pick a few pages, and write from them. A page that cannot be crawled, indexed, and read never enters that process. Google's own guide answers whether SEO is still relevant with "In short, yes!"
Below: what classic SEO still does, the four new jobs, what to skip, and a five-minute check. Each claim links to its source. Where I found no published answer, I say so.
What classic SEO still does for AI answers
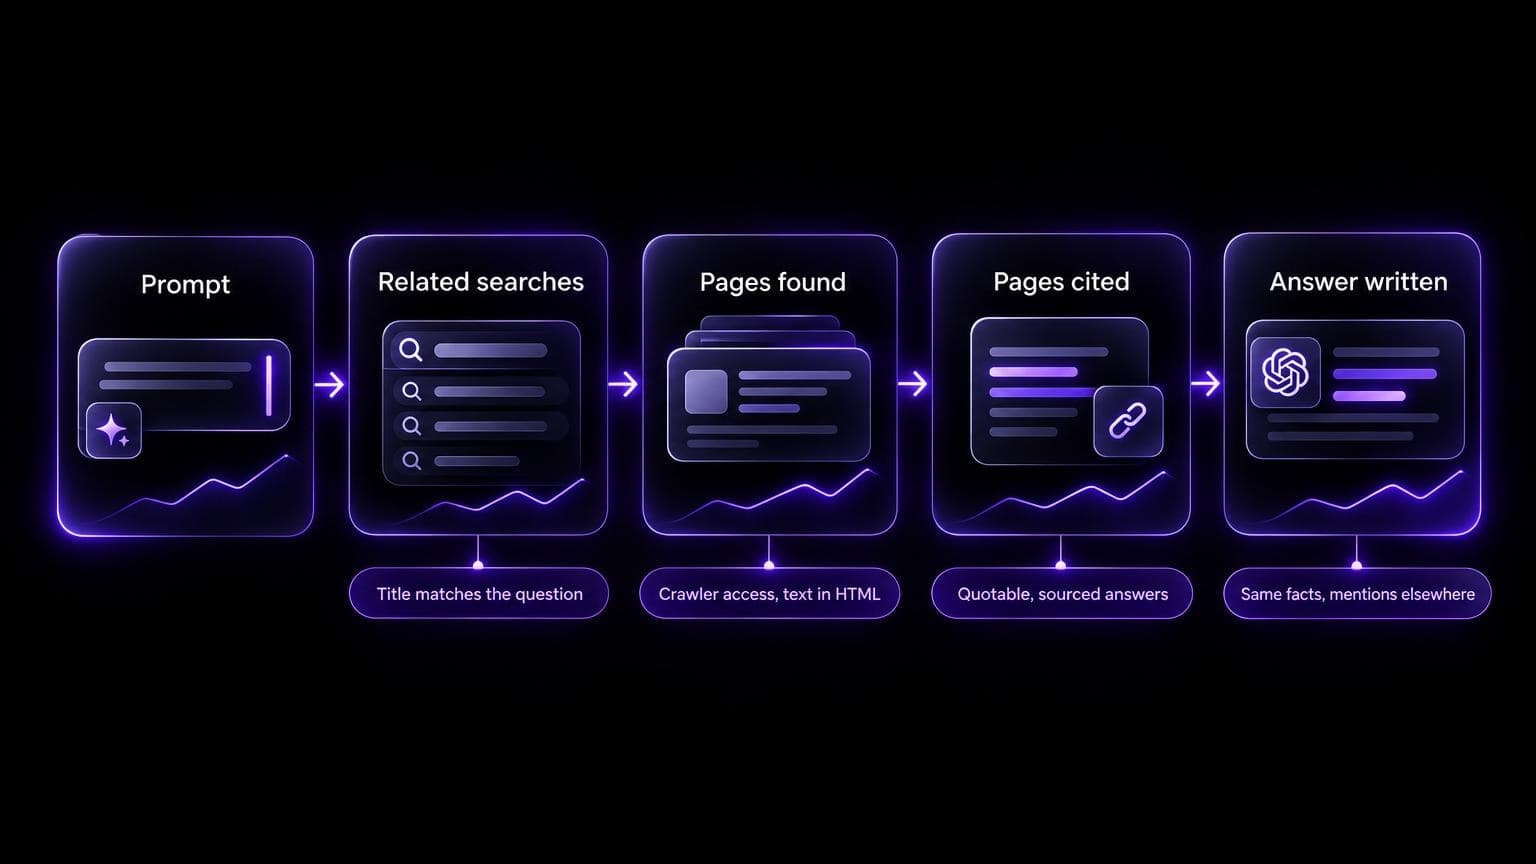
Google's guide to generative AI features (last updated July 2026) says why: AI Overviews and AI Mode run on Google's core ranking systems and retrieve pages from the Search index. A source page must be indexed and eligible for a snippet, and the AI features documentation adds that there are no additional technical requirements.
ChatGPT works similarly. In Ahrefs' study of 1.4 million prompts (April 2026), URLs from its web search channel were cited 88.46% of the time, and URLs from its Reddit feed 1.93%.
Cited pages are often not in the top 10 for the keyword. Ahrefs found that on average 12% of the links that ChatGPT, Gemini, Copilot, and Perplexity cited were in Google's top 10 for the same prompt, and that 37.9% of AI Overview citations were in the first 10 blocks of the results page, where each SERP feature counts as a block. Google's guide describes query fan-out: the model writes several related searches and retrieves pages for each one. Your page competes on the sub-questions, not only on the head keyword.
| Classic SEO task | Status for AI answers | Evidence |
|---|---|---|
| Indexing and crawl access | Required | Google: a source page must be indexed and eligible for a snippet |
| Main content as text in the HTML | Counts for more | Most AI crawlers did not run JavaScript in Vercel's 2024 data |
| Clear titles and readable URLs | Counts | Ahrefs: ChatGPT cited search results with natural-language URL slugs 89.78% of the time, against 81.11% without |
| Backlinks | Counts for less than you expect | Weak correlation with AI mentions in the Ahrefs brand study |
| A page for each keyword variant | Stop | Google: separate pages for each query variation, made to manipulate rankings or AI responses, break its scaled content abuse policy |
See also AI SEO vs traditional SEO.
Let the AI crawlers in
Each engine has its own search bot, and some have several bots with different jobs.
| Engine | Bot that decides search visibility | What the vendor says |
|---|---|---|
| ChatGPT | OAI-SearchBot | OpenAI: a site that opts out is not shown in ChatGPT search answers, though it can still appear as a navigational link. GPTBot is a separate bot for model training. |
| Perplexity | PerplexityBot | Perplexity: allow it to appear in its results. It is not used for model training. |
| Google AI Overviews and AI Mode | Googlebot | Google: robots.txt for Googlebot controls crawling. A Search Console setting can exclude a site from AI Overviews and AI Mode. Google-Extended covers Gemini training and grounding in the Gemini apps, and does not affect inclusion or ranking in Search. |
| Copilot | Bingbot (my inference) | Microsoft: Copilot is powered by Bing's search index. No Microsoft page linked here names a crawler, so I read Bingbot as the one to allow. |
This robots.txt lets the search bots in and treats training as its own choice. OpenAI and Perplexity say a change can take about 24 hours to apply.
# Search bots: let them crawl so the site can appear and be cited
User-agent: OAI-SearchBot
Allow: /

User-agent: PerplexityBot
Allow: /

# Training bot: a separate choice. Blocking it does not remove you from ChatGPT search.
User-agent: GPTBot
Disallow: /
A bot with no group of its own follows the User-agent: * group (RFC 9309), so an old blanket Disallow: / under * blocks every AI bot that you never named. The live robots.txt of aiseotracker.com on 2 October 2026 names none of OAI-SearchBot, PerplexityBot, GPTBot, Googlebot, or Bingbot, so all of them follow User-agent: *, which allows everything except /api/events.
Your CDN can block a bot before robots.txt matters. Since 1 July 2025, Cloudflare asks each new domain whether to allow AI crawlers, and it describes blocking as the default. OpenAI and Perplexity ask you to allow their published IP ranges (OpenAI, Perplexity).
Put the facts in the HTML
Googlebot renders JavaScript. In December 2024, Vercel measured crawler traffic on its network and found that the crawlers of OpenAI, Anthropic, and Perplexity did not run it. That data is almost two years old, and OpenAI and Perplexity do not say whether their bots run JavaScript, so treat Vercel's result as the safe assumption.
Price, features, and the answer to the main question must be in the server response. Microsoft gives the same rule: do not hide important answers in tabs or expandable menus, or put key information only in images or PDFs. Browser agents also read screenshots, raw HTML, and the accessibility tree (web.dev).
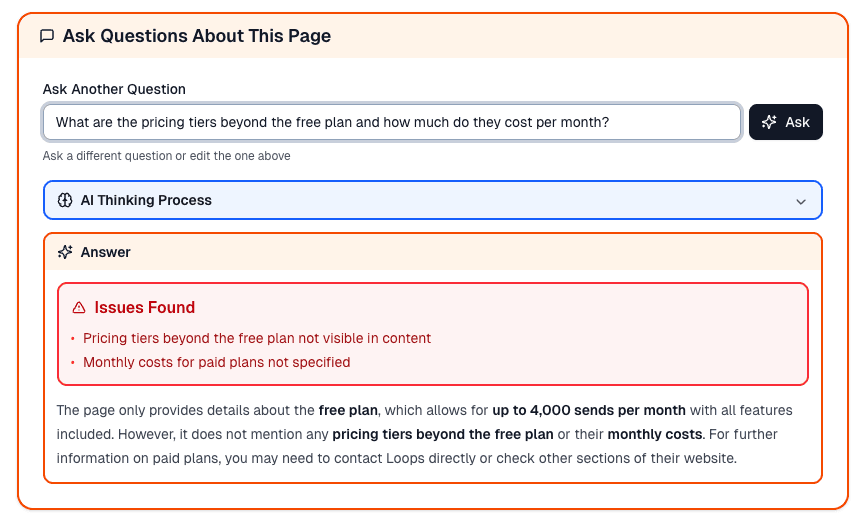
The free Page Inspector shows what AI can read on a page. In our Loops.so case study, a pricing slider left only the Free plan in the text it read. On 2 October 2026, loops.so/pricing gave a browser user agent HTML with no dollar amount, and gave the OAI-SearchBot user agent a text file listing 16 priced tiers. So test with the bot's name.
Create Content That AI Actually Cites
A retrieved page is not a cited page. In the Ahrefs ChatGPT study, about half of the URLs that ChatGPT retrieved were cited, and the cited pages matched the prompt, and the sub-queries ChatGPT wrote, more closely. I have not found a public description from OpenAI or Google of why one retrieved page is cited over another. The public evidence supports five habits (more in how to get cited in AI answers).
- Say something only you can say. Google's guide says unique, non-commodity content will likely influence your presence in AI search in the long run more than any other suggestion in the guide. A first-hand review is its example.
- Name the sub-questions in the title and headings. In Google's fan-out example, a question about fixing a lawn full of weeds can fan out into searches for the best herbicides, weed removal without chemicals, and weed prevention. List the related questions a buyer would ask next. Give each a heading, not a thin page of its own.
- Answer first under each heading. Microsoft says that Copilot breaks a page into smaller pieces and evaluates each piece, so question-and-answer pairs, lists, and tables can be reused. Google says AI needs no special format, so keep it ordinary editing.
- Add evidence and link it. In the GEO paper (KDD 2024), adding citations, quotations, and statistics raised a page's visibility in generated answers by 30 to 40% on the paper's position-adjusted word count metric. The benchmark used an engine built on GPT-3.5, so read the result as a direction.
- Keep the page current. Microsoft tells site owners to update pages regularly and to use IndexNow. Freshness alone does not win: in the Ahrefs data, the median cited page from web search was about 500 days old.
Keep your brand facts consistent
An AI answer describes your company in its own words, from several sources. If your site, a directory, and an old review disagree on your price or product, the model has to choose.
I have not found vendor documentation on how a model resolves a conflict between sources, so this section has no number. The guidance that exists points one way. Google: structured data must match the visible text, and Merchant Center and Business Profile information must be up to date. Microsoft: align text, images, and video so they represent the same entities, products, and concepts.
The work is dull and cheap:
- Write one sentence that says what the product is and who it is for. Use the same category noun on your site, your profiles, and each directory listing.
- Put price, plan limits, and integrations in plain text on one page, with a date.
- Ask each engine what your product is and what it costs. If the answer is wrong, check the cited sources, and correct the old facts you control.
LLM SEO covers the positioning side of this in more depth.
Earn mentions on pages you do not own
Links were the off-page signal of classic SEO. For AI answers, the evidence points at mentions. Ahrefs compared 75,000 brands (December 2025) with how often ChatGPT, AI Mode, and AI Overviews mentioned them.
| Factor | Correlation with AI mentions |
|---|---|
| Brand mentions on YouTube | About 0.74 |
| Brand mentions on web pages | 0.66 to 0.71 |
| Number of pages on the site | About 0.19 |
| Number of backlinks | Very weak |
These are correlations, and large brands have more of everything. My reading is narrower: more pages on your own site is the weakest use of the next hour of work.
Reddit made up 67.8% of the URLs that ChatGPT retrieved and did not cite (Ahrefs). Ahrefs reads this as ChatGPT learning from Reddit, then citing another source. Google's guide warns that inauthentic mentions are not as helpful as they seem, because its spam systems apply to AI features too. Do not buy mentions. Do this instead:
- Run the prompts your buyers ask. Write down each domain the engines cite.
- Sort the domains by type: listicles, review sites, YouTube videos, forum threads, news.
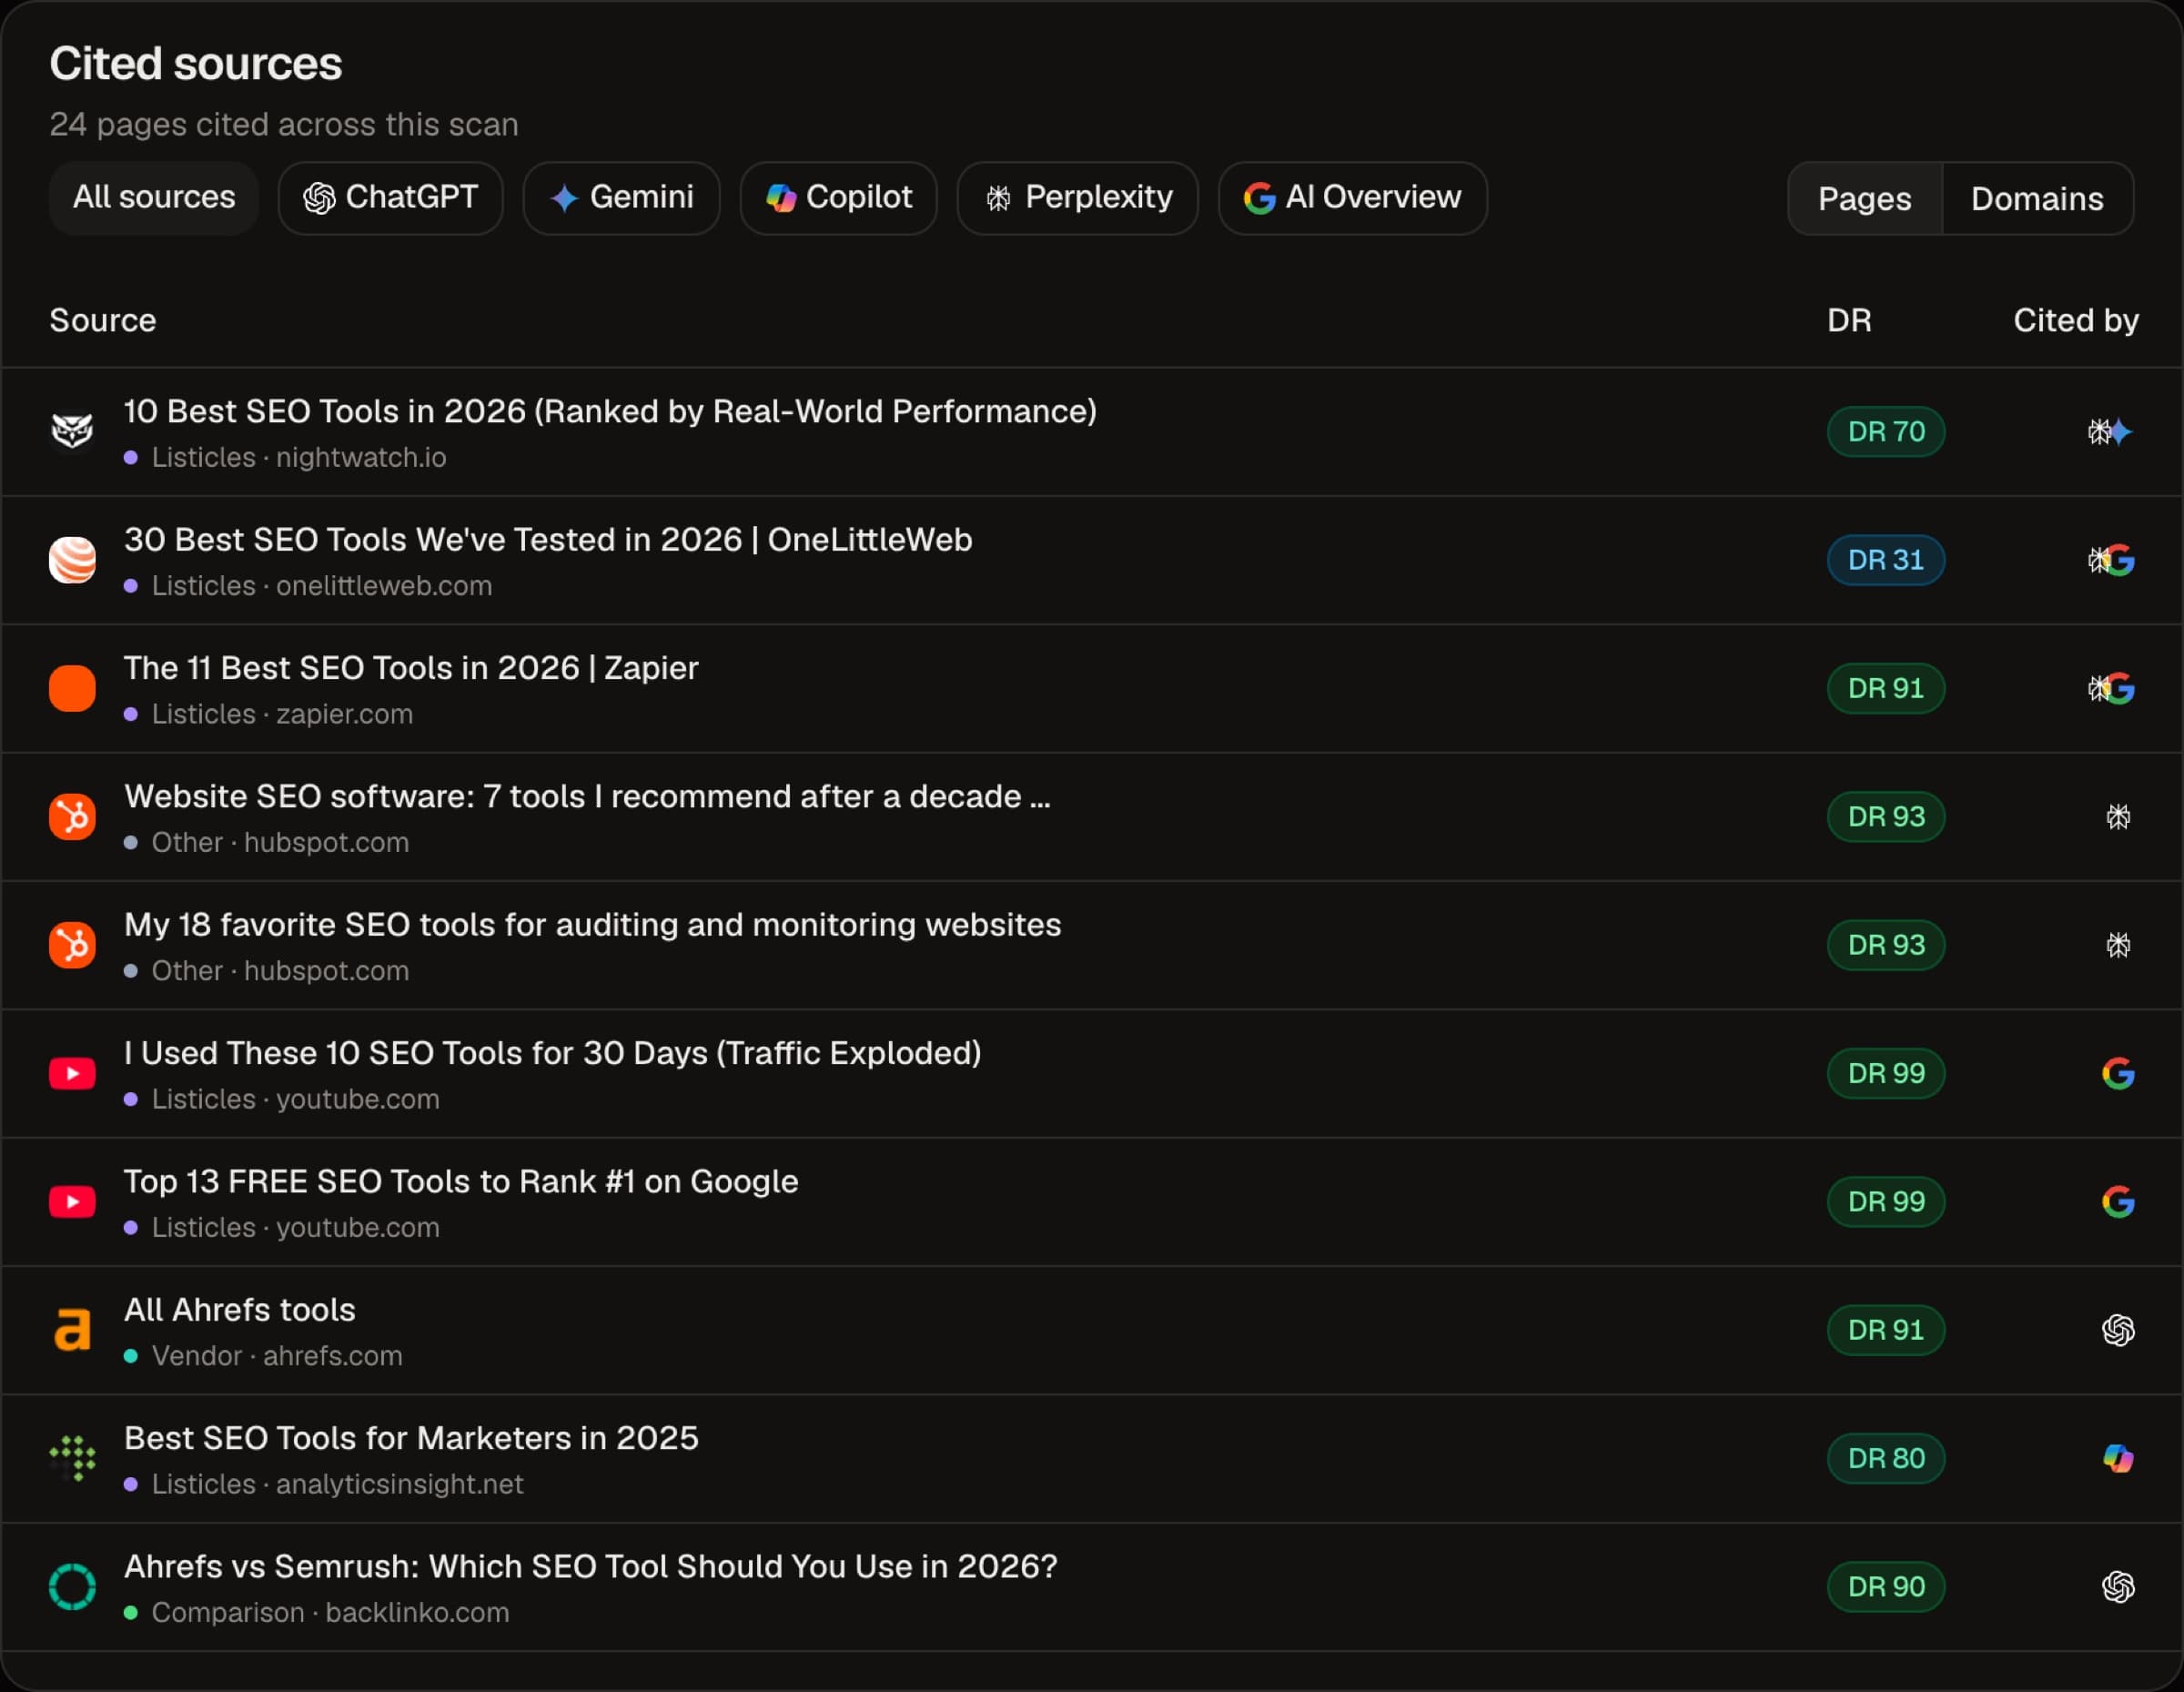
- Go where the citations already are: pitch the listicle author, answer the thread, make the video.
Steps 1 and 2 on our own data: the AI SEO Tracker leaderboard scanned "best SEO tool" on 24 September 2026. Its cited-sources table lists 24 pages: 14 labelled listicles, 3 comparisons, and 1 vendor page. Across all 343 categories, the cited-pages card showed 77% listicles on 2 October 2026. These are product-comparison prompts, and the data shows what was cited, not why. How to get into AI visibility listicles covers the outreach.
What you can skip
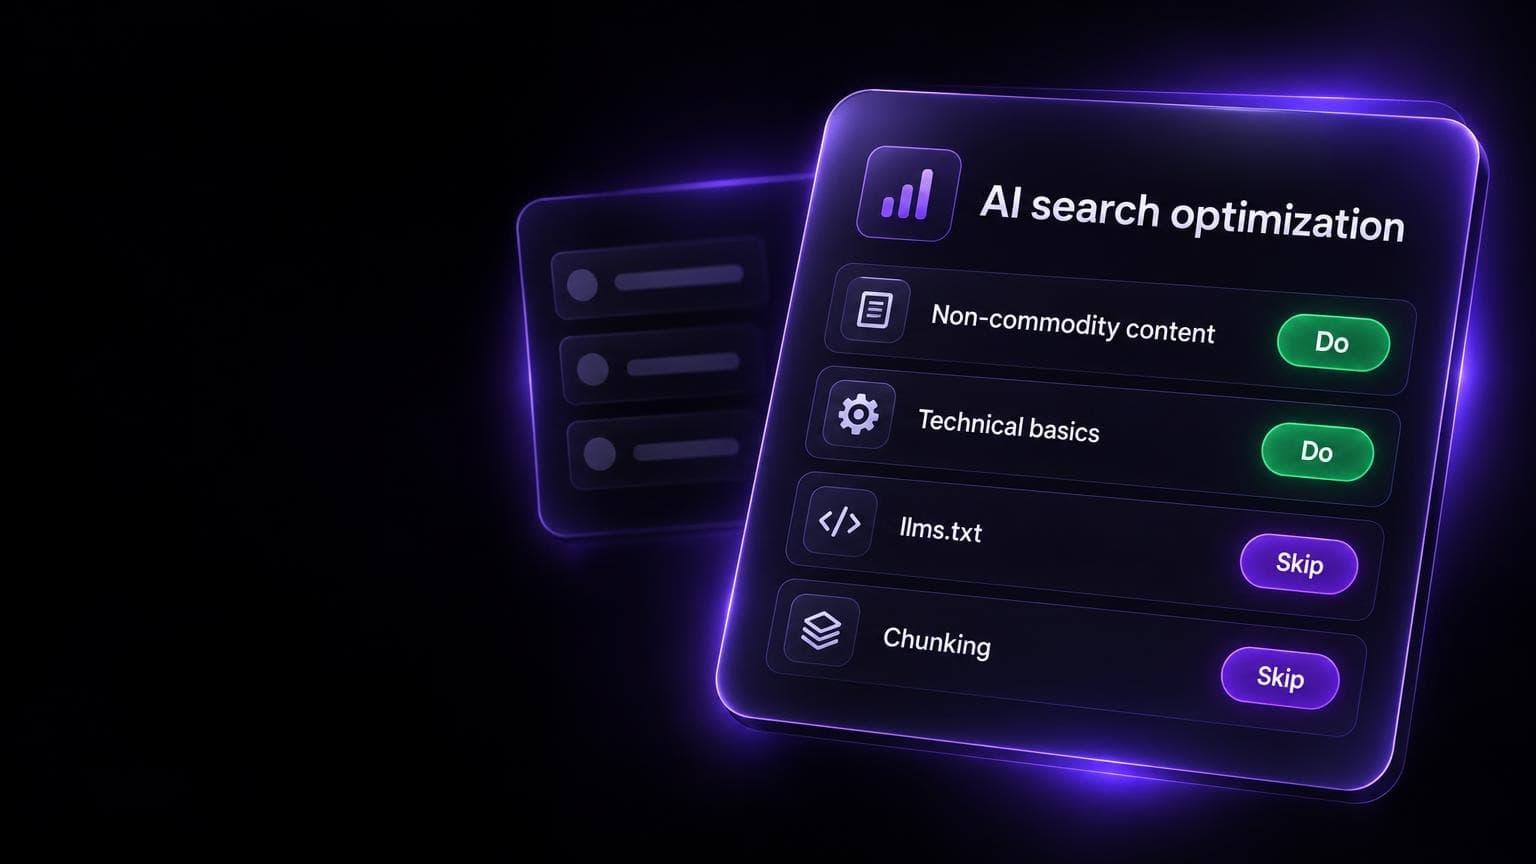
Google's guide lists tactics that you can ignore for Google Search: llms.txt and other special files, chunking, rewriting content in a style made for AI, and overfocusing on structured data.
| Advice you will read | What the source says |
|---|---|
| Add an llms.txt file. | Google: Search does not use it. Keeping one neither helps nor harms there. |
| Refresh pages every quarter, because citations drop after three months. (LLMrefs, "from our data", no method shown) | Ahrefs: the median page that ChatGPT cited from search was about 500 days old, and inside one prompt's retrieved pages the freshest tended to be dropped. |
| Allow GPTBot so ChatGPT can cite you. | OpenAI: GPTBot is for training. OAI-SearchBot controls search results. |
| Add schema types for AI. | Google: not required, and no special schema. Microsoft says schema helps search engines and AI systems understand a page. The crawler pages of OpenAI and Perplexity do not mention schema. |
My position: keep the schema your CMS writes, make sure it matches the page, and do not start a schema project. An llms.txt file costs minutes to write, so add one if you want it. Do not expect it to move citations. More in AI search optimization.
How to check that it works
A rank tracker does not show any of this.
A five-minute access check
Run these against your site. Replace example.com with your domain.
# 1. Which rules apply to the search bots? No named group means a bot follows "User-agent: *".
curl -s https://example.com/robots.txt | grep -i -E "OAI-SearchBot|PerplexityBot|GPTBot|Googlebot|Bingbot|User-agent: \*"

# 2. Is a fact from your page in the HTML? Replace $49. No output means JavaScript loads it.
curl -s https://example.com/pricing | grep -o -E '.{0,30}\$49.{0,30}'

# 3. Does the server answer a search bot's user agent? A 403 means a CDN or firewall rule blocks it.
curl -s -o /dev/null -w "%{http_code}\n" -A "Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/131.0.0.0 Safari/537.36; compatible; OAI-SearchBot/1.4; +https://openai.com/searchbot" https://example.com/pricing

# 4. Does a header or meta tag limit snippets? Look for nosnippet or max-snippet:0.
curl -sI https://example.com/pricing | grep -i x-robots-tag
curl -s https://example.com/pricing | grep -i -o 'name="robots"[^>]*'
Output for aiseotracker.com on 2 October 2026: step 1 prints only User-agent: *, step 2 finds the $49 price, step 3 returns 200 for the OAI-SearchBot and PerplexityBot user agents, and step 4 shows no X-Robots-Tag header and a robots meta tag with max-snippet:-1.
Google says that nosnippet and max-snippet:0 keep a page's text out as direct input for AI Overviews and AI Mode. Step 3 tests user-agent rules only: Perplexity's Cloudflare steps match on both the user agent and the IP range, so a 200 does not prove that the real bot gets in. Search your server logs for the bot names.
Track it with a fixed prompt set
Google's guide points to a Generative AI performance report in Search Console (see how to track Google AI Overviews). The Bing AI Performance report (public preview since February 2026) covers Copilot and Bing's AI summaries. For ChatGPT and Perplexity, I know of no first-party report that every site owner can open. So you run the same prompts on a schedule and record whether you were mentioned, whether you were cited (a citation is not a backlink), and which URL. How to measure AI brand visibility has the method.
One check proves nothing, because chatbot answers differ from run to run (Squarespace says the same). Google says no third-party tool has access to its internal ranking or AI systems, so a tracker, ours included, samples answers. Record the results before you change anything.
You can keep the prompt set by hand in a spreadsheet. AI SEO Tracker does it as a report: $49 one time, up to 50 prompts written from your site, scanned daily for 7 days on ChatGPT, Perplexity, Gemini, Copilot, and Google AI Overviews, with the sources each engine cited.
Your Top Questions About SEO for AI, Answered
How do you do SEO for AI?
Start with classic SEO: a page that is indexed, readable, and clearly titled. Then do four jobs: let the search bots crawl, write answers a model can quote, keep brand facts the same, and earn mentions. Run the access check first.
What is SEO for AI called?
It is also called answer engine optimization (AEO), generative engine optimization (GEO), LLM SEO, and AI SEO. Google says that from its side this is still SEO. AI SEO vs LLM SEO vs GEO vs LEO compares the names.
Is SEO still worth it with AI?
Yes. Google's guide says SEO best practices still apply to its AI features, and a page that search does not return is rarely cited by ChatGPT.
How do I format a blog post so AI search engines can read and cite it?
Use ordinary HTML and careful editing. Write a title that states the question, with a plain-word URL slug. Put the answer in the first paragraph, and give each sub-question an H2 or H3 with its answer directly below. Link each number to its source, and keep key facts in the server-rendered HTML, not only in images, tabs, or PDFs.
Will an AI answer give my site a backlink?
No. A citation is a source link inside one answer, shown to the person who asked. It can send a visit. It is not a link from a page on another site. Some answers name a brand and show no link, so count mentions and citations as two numbers. See AI citations.
Should I block GPTBot?
A block on GPTBot is a decision about model training. It does not remove you from ChatGPT search answers, because OAI-SearchBot controls that. I have not seen public data on whether a training block changes what a model says about a brand later.